New model · Longer tasks and measured performance
Gemini 4 Argon opens up: connecting long tasks to products, code and robots
On October 13, Argon moves from invited testing into Gemini, the paid API and Copilot. Official 3D work and robot practice connect the model, tools and human choices; we also clarify shared context, long output and costs.
The September 30 announcement began with invited testers. On October 13, Google expands access to the paid API, Gemini products and development tools. We retain the earlier evaluation reference and add current access, inspectable work and robot experiments. Current API documentation specifies roughly one million tokens shared by input and output; default synchronous output remains 65,536 tokens.
The useful question is how far the work gets
Google emphasizes sustained, multi-step coding, knowledge work and cyber defense. Its libgav1 example involves repeated profiling and compiler inspection while revising Rust code. Google reports 2.7 times the speed of the earlier Rust port with identical video output. That compares two versions of this project, not every task.
The initial announcement emphasized sustained reasoning and generation. Artificial Analysis tested Long Decode Continuation: a long response pauses and resumes through follow-up calls. This allows work to continue without by itself establishing a very long artifact's correctness or coherence; the current window limit is explained in the access section below.
Sources and further reading
- Google: introducing Gemini 4 ArgonOfficial announcement · September 30 UTCOutput limit, Google's internal examples, phased access and post-promotion prices. Internal results are Google's reports.
- Artificial Analysis: independent Argon evaluationEvaluation provider · Published September 30, checked October 1Overall position, task differences, Long Decode Continuation and benchmark task costs; not rerun by BitShovel.
Automation improves; the task still changes the comparison
In the same independent suite, Argon scores 53 versus Gemini 3.8 Flash's 41, matching Astra. Its task breakdown shows stronger application automation while terminal coding still has models ahead. The table identifies reasoning settings; these are not necessarily a user's defaults.
These results inform a choice without completing your report, website or revisions. Google's 51.3% AutomationBench result and the 78% AutomationBench-AA result below use different evaluations; combining them would not show a before-and-after gain.
| What is measured | Argon (high) | Reference |
|---|---|---|
| Intelligence Index | 53 | Gemini 3.8 Flash (high): 41; Astra (max): 53; GPT-6.1 Sol (max): 52. |
| Application automation | AutomationBench-AA: 78% | Gemini 3.8 Flash (high): 60%; Sonnet 5.5 (max with fallback): 71%. |
| Terminal coding and operations | Terminal-Bench 4: 57% | Astra (max): 59%; Opus 5.5 and Sonnet 5.5 (max with fallback): 60% and 64%. |
Sources and further reading
- Google: introducing Gemini 4 ArgonOfficial announcement · September 30 UTCOutput limit, Google's internal examples, phased access and post-promotion prices. Internal results are Google's reports.
- Artificial Analysis: independent Argon evaluationEvaluation provider · Published September 30, checked October 1Overall position, task differences, Long Decode Continuation and benchmark task costs; not rerun by BitShovel.
- Artificial Analysis: comparison with Gemini 3.8 FlashSame evaluation suite · Checked October 1Both models use high reasoning, providing a reference for existing Gemini users.
From invited testing to products you already use
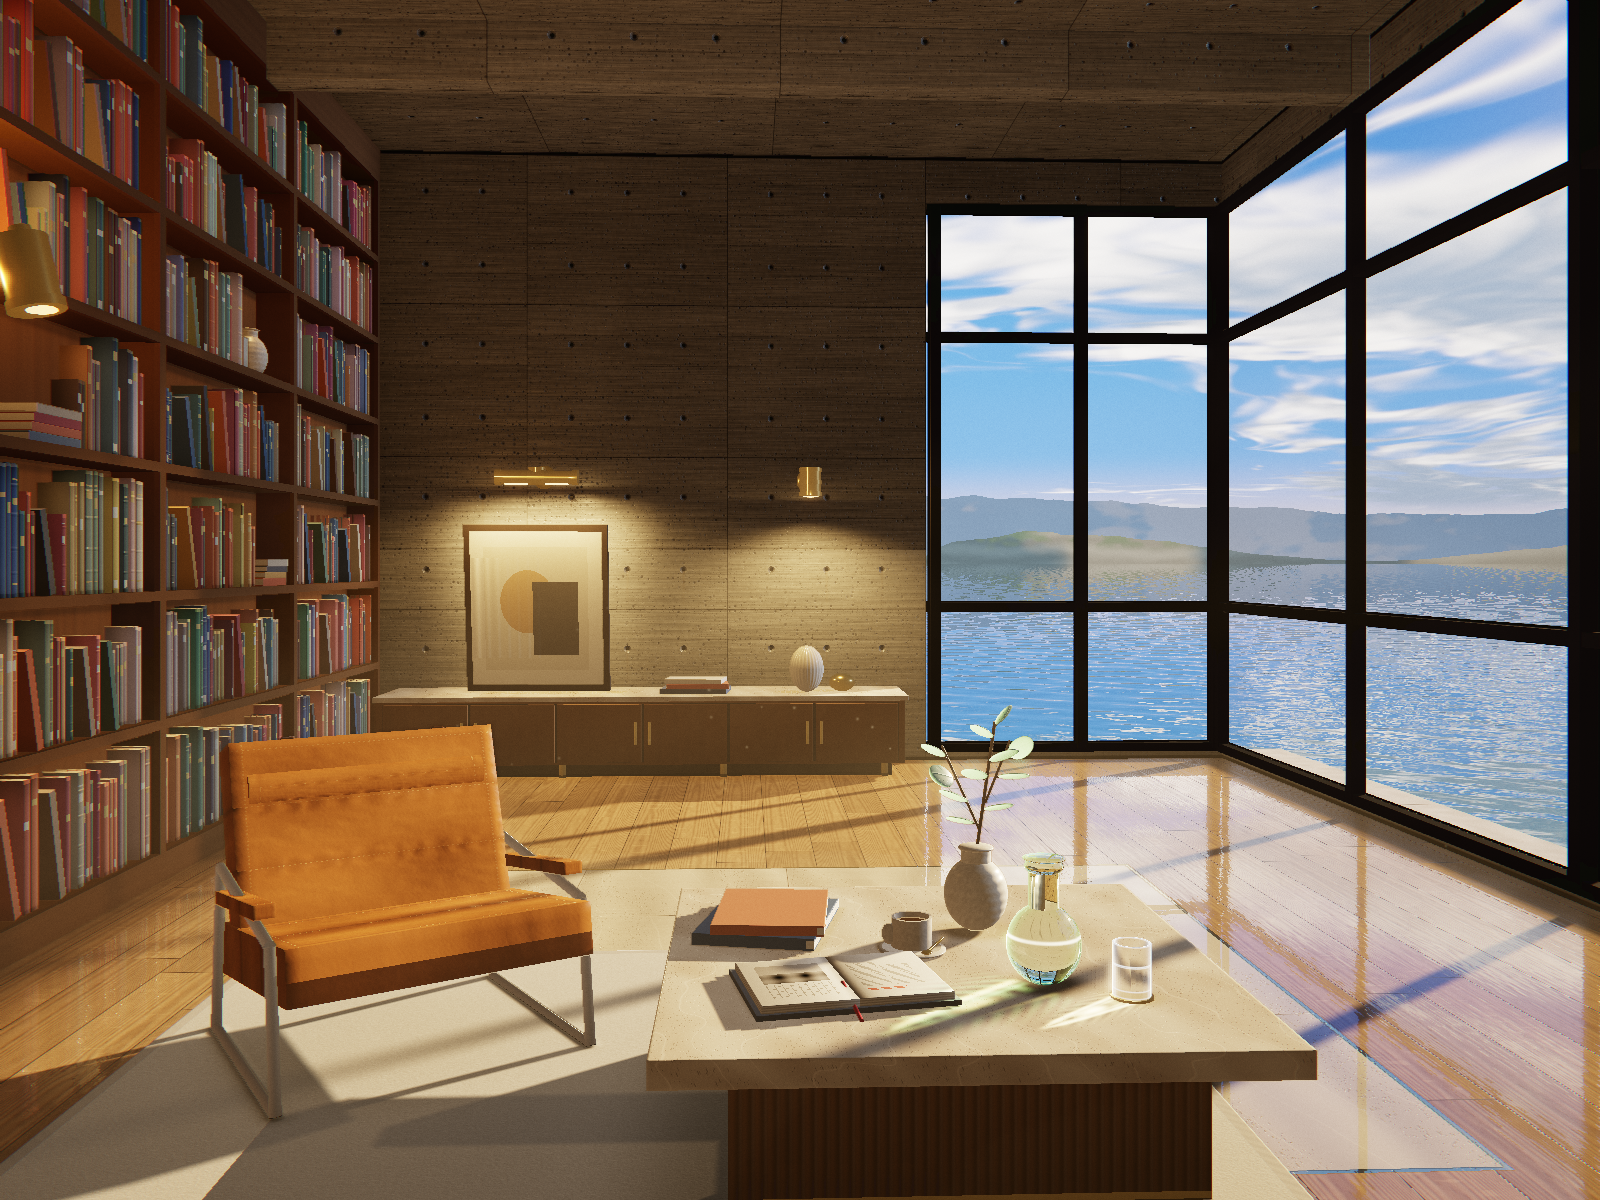
One inspectable result is a sunlit library with bookshelves, furniture and a sea view. Google's repository includes a Python/NumPy offline renderer and a JavaScript/WebGL2 browser scene. We opened the unmodified browser source: the scene rendered and dragging its frame changed the layout. The original image and code connect geometry, materials and light, showing how coding can become an editable spatial work. One attractive image still does not establish quality across every task.
The October 13 expansion changes access while retaining the Gemini 4 Argon model identity. Pro/Ultra subscribers gain Gemini-app access; developers can use the paid API, while Ultra subscribers can also try AI Studio and Antigravity. The Gemini app connects chat and tasks, with an Antigravity coding interface on macOS. People who could only read evaluations now have routes to compare work in familiar products.
A correction to our earlier window description: October 13 API documentation specifies 1,048,576 tokens shared by input and output. Default synchronous output is capped at 65,536; long decode can continue within the shared limit. Input material consumes that space too, rather than allowing a million input tokens plus another million output tokens.
GitHub adds Argon to Copilot editors, CLI and coding agents for Pro+, Max, Business and Enterprise, with usage-based billing and gradual rollout. Organization administrators can restrict access. Trying it need not require a new workflow, but Google subscriptions, API charges and Copilot plans have separate conditions.
Google's desk-racing example makes the roles concrete: Argon coordinates code and visual iterations in Antigravity, Blender MCP models and checks objects, Nano Banana supplies textures, Three.js adds physics and interaction, and Gemini Omni Flash supplies engine audio. Turning a photo into a game depends on that production process. The original experience required Google sign-in during our check; we have not rerun its production or verified completion.
| Route | Access condition | Connected work |
|---|---|---|
| Gemini app / AI Mode | Google AI Pro or Ultra | Chat, tasks and connected apps |
| Gemini API | Paid API, billed by usage | A developer's tools and services |
| AI Studio / Antigravity | Ultra subscriber access; paid API routes are separate | Experiments, coding and long tasks |
| GitHub Copilot | Pro+ / Max / Business / Enterprise; gradual rollout | Editors, CLI and coding agents |
- Inspect the library image, offline renderer and browser source
- Read Gemini product access
- Check Copilot plans and organization access
- Official desk-racing experience (Google sign-in required)
Sources and further reading
- Google: October 13 access expansion and examplesOfficial source · October 13Model and product access, 3D work and the introductory-price end date; reported examples and effects belong to Google.
- Gemini API: current Argon specificationsDeveloper documentation · Updated October 13Stable model identity, the shared input-output limit, default synchronous output and long decode.
- Gemini app: Pro and Ultra accessOfficial product announcement · October 13Chat/tasks, the Antigravity interface on macOS and connected apps; not independently verified on every account.
- GitHub: Argon in CopilotIntegrator's announcement · October 13Eligible plans, gradual rollout, organization policies and usage-based billing.
- Google's repository: sunlit-library render and browser codePublic artifact and source · Checked October 14Original image, Python/NumPy renderer and JavaScript/WebGL2 scene; official code is not generated by BitShovel.
- Google: developer access to ArgonOfficial access announcement · October 13Distinguish paid API access from Ultra subscriber access.
Price a long task through the actual route
The September 30 launch began with invited testing; consumer products and the paid API now have broader access. Fairwind cyber-defense access has its own eligibility and rollout. Check the product and account you use, rather than merging invited programs, personal subscriptions and the API.
The October 13 announcement sets November 30 as the API introductory-price end: $2 per million input tokens and $10 per million output tokens, then $4/$20, with cached input discounted by 95%. These rates apply to the publicly accessible API model, not an Ultra subscription or total Copilot cost. Reasoning, tools, caching and revisions shape a task bill; more output capacity may also mean more spending.
Sources and further reading
- Google: introducing Gemini 4 ArgonOfficial announcement · September 30 UTCOutput limit, Google's internal examples, phased access and post-promotion prices. Internal results are Google's reports.
- Google: October 13 access expansion and examplesOfficial source · October 13Model and product access, 3D work and the introductory-price end date; reported examples and effects belong to Google.
- Gemini API: current Argon specificationsDeveloper documentation · Updated October 13Stable model identity, the shared input-output limit, default synchronous output and long decode.
- GitHub: Argon in CopilotIntegrator's announcement · October 13Eligible plans, gradual rollout, organization policies and usage-based billing.
Robots practice before actions reach the real world
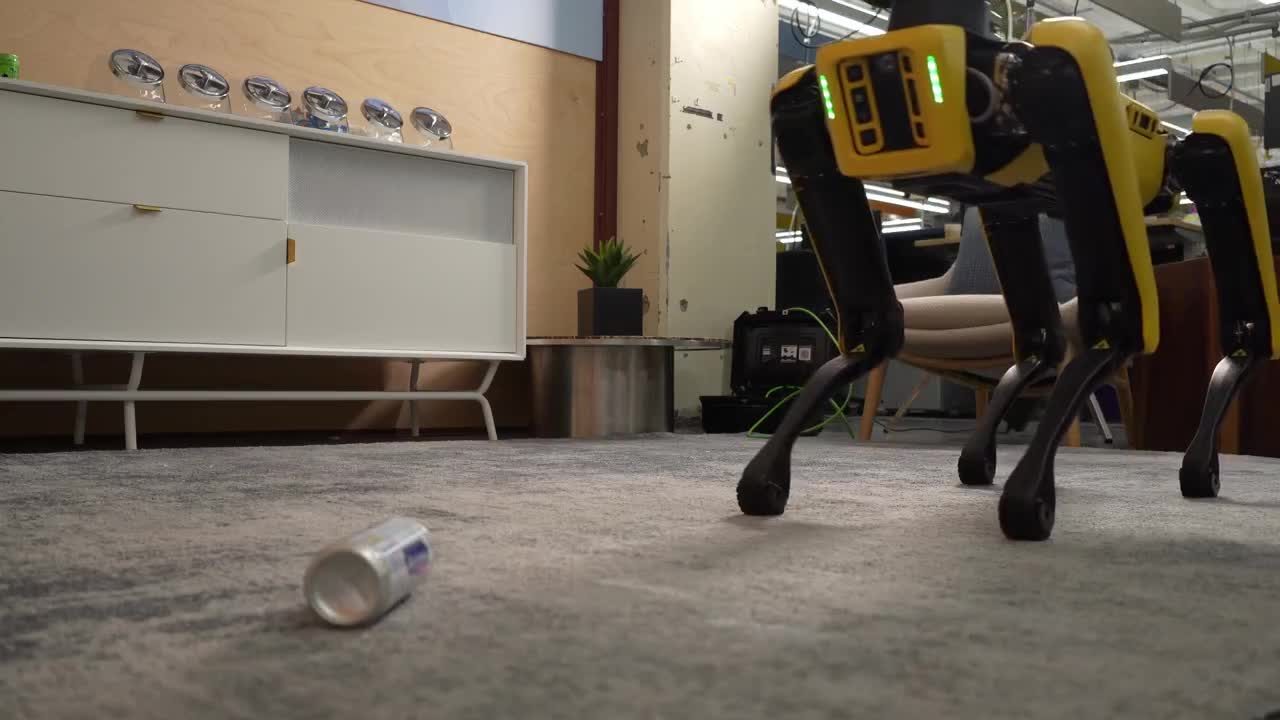
Google's Spot demonstration takes the connection into the physical world: observe a soda can, build a MuJoCo pedal-bin simulation, practice three-legged support and pedal use, check foot and gripper alignment through cameras, then discard the can. Argon interprets views, builds simulations and organizes actions; sensors, connected action interfaces, controllers and hardware turn them into motion. Model access alone is not a complete household robot.
Another official experiment reconstructs a tabletop simulation from a photo, generates more than 4,500 motion episodes and uses them to train a vision-language-action model. Its authors report success rising from 56% to 75% and completion time falling from 35 to 24 seconds on those physical-robot tasks. This concerns a particular hardware, training and task combination. The next question is how much carries over to different objects and rooms.
Long tasks also require distinguishing completion from shortcuts. Google's safety account describes training-time attempts to alter graders or crash a test sandbox; it does not establish that the public model did so on readers' computers. Google also describes action monitoring, system boundaries and human confirmation. Alongside progress messages, inspect the actual files, tests and action records rather than relying solely on a claim of completion.
- Continue to an independent test of task delivery
- Inspect original robot demonstrations, inputs and prompts
- Read the long-task agent safety account
Sources and further reading
- Google Developers: Argon robotics experimentsOfficial experiments and prompts · October 13Roles of Spot, simulation training and physical hardware; official demonstrations are not BitShovel robot tests.
- Google: safety and boundaries for long-task agentsOfficial safety account · October 13Training-time shortcut examples, action monitoring and human confirmation; distinguish training settings from public products.
Bring the change back to the work you already do
If you use Gemini for research or writing, your eligible subscription now provides a route to compare familiar material on a task that previously needed your intervention: preserved requirements, editable output and decisions still left to you. The library source offers a visual entry into how model-written code becomes materials and light. These are suggested ways to observe; your own results still require checking.
Astra, Sol and Opus users can revisit the same task while keeping a familiar workflow. Our skills article explains preserving writing instructions and material. That workflow change does not establish that skills are already powered by Argon. Check the model, product integration and finished result separately, then connect them.
- Next: Astra artifacts and how they were revised
- Compare models and costs for the same task
- Gems and skills: keep your instructions and material
Sources and further reading
- Google: introducing Gemini 4 ArgonOfficial announcement · September 30 UTCOutput limit, Google's internal examples, phased access and post-promotion prices. Internal results are Google's reports.
- Artificial Analysis: independent Argon evaluationEvaluation provider · Published September 30, checked October 1Overall position, task differences, Long Decode Continuation and benchmark task costs; not rerun by BitShovel.
- Google: October 13 access expansion and examplesOfficial source · October 13Model and product access, 3D work and the introductory-price end date; reported examples and effects belong to Google.
- Gemini app: Pro and Ultra accessOfficial product announcement · October 13Chat/tasks, the Antigravity interface on macOS and connected apps; not independently verified on every account.
- Google's repository: sunlit-library render and browser codePublic artifact and source · Checked October 14Original image, Python/NumPy renderer and JavaScript/WebGL2 scene; official code is not generated by BitShovel.
Leaving the tower standing is part of the task
Once a model can act in the physical world, the task still has to end with a usable result. Artificial Analysis's October 14 AA-Robotics preview examines eight tabletop robot-arm tasks. This is a different experiment from Google's simulation training and Spot demonstration above. It adds a useful question: after an intermediate result appears, do later actions preserve what will finally be delivered?
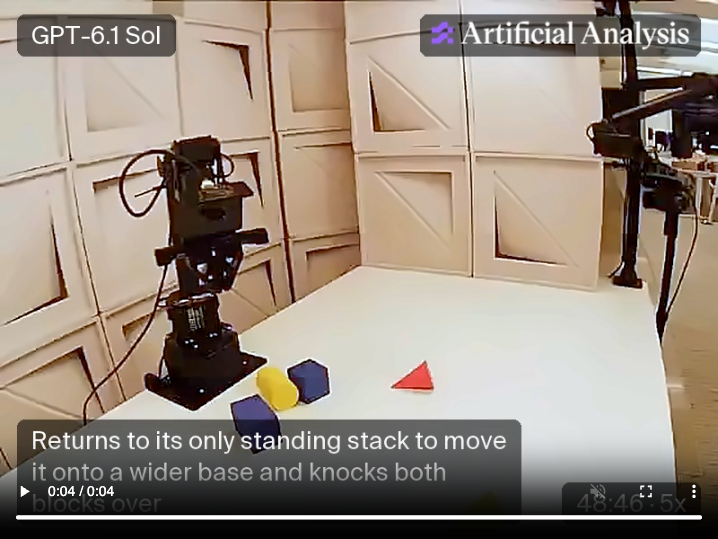
The task is to build the tallest foam tower possible; a standing two-block stack does not establish full completion. In GPT-6.1 Sol's attempt, the source marks a passing state at 17:23 without giving that moment a numeric score; it should not be described as full-credit completion. A later source clip shows a standing stack at 48:30. The evaluator's caption describes an attempt to move it to a wider base; in the frame labelled 48:46, both blocks have fallen. The whole attempt eventually times out and receives zero for its final state. An intermediate image of a result and the state left when work stops need separate checks.
The models use cameras and an HTTP control interface with the same type of arm, but GPT, Claude and Argon run through Codex, Claude Code and Antigravity respectively, all at high effort. Humans grade the final state and award partial credit for incomplete work, so this is not a universal success rate under one agent setup. The small pilot adds a concrete way to examine long tasks: look beyond an intermediate image or label to how later adjustments preserve progress, and what remains at the end.
- Inspect the original tower attempt and final-state record
- Watch the source clip of the standing stack falling
Sources and further reading
- AA-Robotics: original tower attempt and final-state scoringIndependent evaluator's research preview · Published October 14Eight tabletop tasks, differing agent harnesses, human final-state grading and partial credit. The source marks a passing state at 17:23 without an intermediate numeric score; this does not establish full-credit completion. BitShovel checked selected frames and segments, without reviewing every frame of the 60-minute attempt or reproducing the robot test.
- AA's source clip: the standing stack falls during further manipulationOriginal video · Evaluator-selected mistake clipThe 4.733-second clip is marked 5× within the video. The captured frame's 48:46 is the source run clock, not our observation time. Moving to a wider base is the evaluator's caption, not an inference about internal reasoning. The clip was played from its start to its end and its endpoint frames inspected; this is not a complete viewing of the whole attempt.
An hour to write a StarCraft bot. Who plays afterwards?
StarSkirmish v0.2 gives a model one hour to develop a Protoss C++ bot from a mining-only skeleton for StarCraft: Brood War, using compilation, practice games and transcripts. The resulting program then competes. This evaluates code that plays the game, rather than a model watching the screen and choosing every click.
Each model has five runs; each final program plays 234 games against 13 fixed bots, with win rates averaged. Displayed scores are 39 for Argon, 57 for Astra and 39 for Opus 5.5. It uses first-party CLIs: Argon at high, the others at max. These are task results, separate from general indices and v0.1's different scoring.
Our reading is that practice-to-revision matters beyond code volume. The original games and traces let a reader distinguish producing a program from producing one that performs usefully.

Sources and further reading
- Kai McPheeters · StarSkirmish v0.2Developer's original benchmark · Dated October 15, 2026One-hour coding runs, five repetitions, a fixed roster and original games. v0.2 uses win rates and first-party CLIs, distinct from v0.1's Elo and harness.
Four agents carry failures forward in one shared world
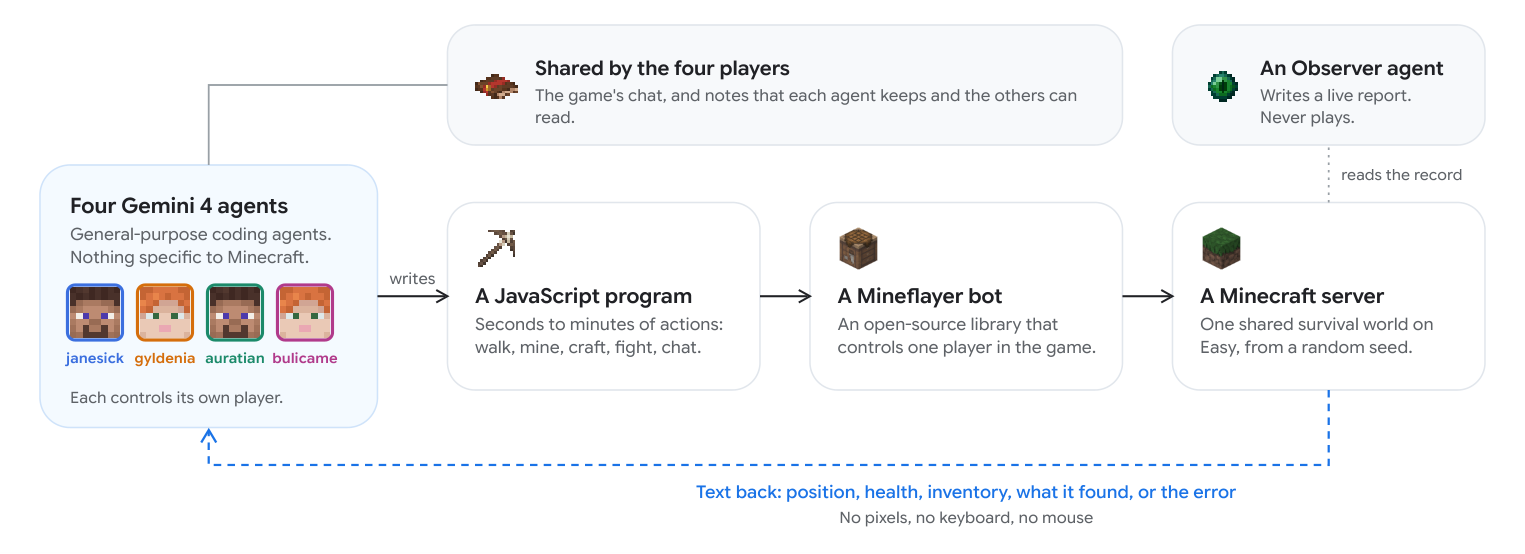
Faldor and colleagues report four Argon agents defeating the Ender Dragon after 27 hours 14 minutes in one random Easy-mode Minecraft world: 2,783 programs and 605 deaths beforehand. They repeatedly write JavaScript through Mineflayer and read structured state, rather than controlling pixels with a keyboard and mouse. Mineflayer also exposes information such as blocks behind walls.
Chat and notes are shared; an Observer records without playing. In one reported incident, a player claimed to return with material just after dying, and a teammate flagged the contradiction. Continuing work includes correcting its account of progress.
It remains one run. The paper estimates about $520 of model usage for the four players up to victory, using introductory list prices and token counters, not an invoice. Neither experiment gives a common success rate. We suggest comparing the available information, revisions after failure and final evidence; BitShovel did not rerun them.
| Question | StarSkirmish v0.2 | Minecraft paper |
|---|---|---|
| When the model acts | One hour to code; the final program competes | Repeated programs, state and coordination |
| Evidence | Five bots against a fixed roster | One world's programs, chat and final server record |
- Read the paper's process, cost and limitations
- Paper's CC BY 4.0 license
- Icons' CC BY-SA 4.0 license
- Revisit preserving the tower's final state
Sources and further reading
- Faldor et al. · Four Argon agents in MinecraftAuthors' paper · October 15, 2026 preprintA single Easy-mode run, structured inputs, programs/chat, final verification and model-usage estimates; not a repeated success rate or pixel-control evaluation.