AI video · Case study
A 24-second drama sample: script, shot decisions and real errors
How a real sample was made from source text, storyboards and generated clips.
Published · Reviewed
Latest addition · Whole-episode reconstruction: from measured numbers to a generatable script
Documented resultA 24-second vertical sample and an actual run log
The creators published script, storyboard, prompts, eight generated clips and edit records; no reach or revenue data for the sample.
Check this resultRead the context and editorial assessment
Watch the result, then trace a shot back through script, visual plan, storyboard and prompt. Published checks, edit points and audio measurements make decisions inspectable.
01
Verified material
Watch the 24-second sample
The creators show the vertical film in their repository README.
ZenStory's repository shows a 24-second vertical sample. Its authors say they started from a 20-chapter source, wrote script and visual plans, developed 21 shots and video prompts, generated eight clips for the third scene, then edited this sample.
This is a sample scene from a larger workflow. Its documented result is a watchable finished segment; the repository does not report its views, client orders or revenue.
Sources for this section: ZenStory drama-skills repository
02
Verified material
One shot from script to motion
The public sample links script, appearance lock, storyboard and video prompt.
The authors use SHOT-EP001-002 as a worked example. The script describes documents being pushed across a desk. A visual plan records appearance, office and prop continuity. The storyboard specifies the start and end while tracing characters, place and props to that plan.
The video prompt condenses appearance into an anchor and spells out observable actions: the paper reaches a fingertip, a cup is lifted, a frown follows and the cup returns to its mark. This is the repository's own shot, not a prompt from Wanyao Tulu Zhuan or a universal recipe.
The original example exposes the full prompt and underlying files. Before reusing a pattern, check model, reference and target length; the useful lesson is how inputs and shot decisions connect.
Sources for this section: Documented real outputs · Open EP001 example
03
Verified material
What the checks actually caught
The authors show a deliberately damaged sample and errors in an actual run.
In a demonstration, the authors deliberately remove a character from the visual basis and shorten a different shot's prompt duration. Their checker catches a missing reference and a duration mismatch. These are intentional test failures, not production incidents.
A separate actual run log records a caption window beyond a cut, wrong delivery dimensions, loudness missing the target after one pass, and a misheard line in transcription. The authors corrected the edit and output, using transcription only for timing while taking subtitles from the script.
Sources for this section: Documented real outputs · Original sample run log
04
Verified material
Why this cut starts at two seconds
The edit sheet records in and out points and why they were chosen.
The published CUT-EP001-008 runs from 2.00 to 7.00 seconds of its source clip. The edit sheet says the opening stare repeated the previous beat, so the cut begins as the body leans forward; the voice ends at 6.82 seconds and the shot holds to 7.00 for the movement to complete.
The transferable point is not a fixed timing recipe. Measure the actual footage, then choose which action and sound must remain. The source files make the judgment inspectable.
Sources for this section: Documented real outputs · Original sample edit sheet
05
Our analysis
Fix scene geography before describing the shot to a model
Read the 68-second opening separately from the October 20 method update: scene relations, camera composition and action load require different checks.
The repository replaced its earlier clip on September 27 with a 68-second vertical opening for episode one of Let You Run the Account. The creator reports twenty shots and approximately RMB 40 for video generation. It covers more narrative than the 24-second third-scene excerpt first shown here, but is not a complete episode, and that figure is not a verified total for labor, images, audio or rework. We played the original GitHub video muted to its 68.5-second end, inspected track metadata and sampled frames showing the office, phone and task panel. We did not audition sound or judge lip sync. The earlier edit sheet and errors remain evidence of the original 24-second run, not this film.
The formal v0.9.1 release on October 20 makes an easily missed step explicit: preserve a scene's geography using fixed objects and character relationships, then describe foreground, background, orientation, screen sides and gaze targets for each camera. Facing each other across a desk describes a relationship; placing the camera in front of the desk, with her back toward it in the foreground and the desk between them, describes the corresponding image. The current EP001 example adds scene-blocking sections. That document is not proof of the 68-second film's shot-by-shot generation or evidence that the September work used the October method.
The creator's same-day Seedance 2.0 report covers one setting and small groups of five-second vertical generations. Abstract relationship wording still placed the pair on the same side of the desk, while a camera-relative foreground/background version produced the intended separation. Another group packed six actions into five seconds: apparent completion compressed later actions into unreadable flashes. The useful questions are where each person stands and which events the audience must actually read, before choosing to split, lengthen or remove unnecessary action. The raw test media is not public, so this is not a playable before/after comparison, and neither these small samples nor endpoint-image similarity guarantees continuity or completed action.
Documented process
Three checks for one scene
A BitShovel reading aid based on creator guidance, not this film's production record or a BitShovel generation test.
Scene geography
Desk, door, windows and character relationships; inspect whether the relationship survives a camera change.
Check the source for this stepCurrent shot
Camera, foreground/background, orientation and gaze target; inspect whether positions and gaze match the intended subject.
Check the source for this stepAction load
Actions, dialogue and reaction the audience must read; inspect whether actions finish legibly, not merely how many occur.
Check the source for this step
Evidence limitA BitShovel reading aid based on creator guidance, not this film's production record or a BitShovel generation test.
 Check visual source ↗
- Watch the creator's 68-second opening
- Read the actual v0.9.1 changes
- Inspect the creator's samples and limits
Sources for this section: September 27: the opening sample replaces the earlier clip · Drama Skills v0.9.1 formal release · Scene blocking and camera-relative composition · Model-behavior observations and execution limits · Shot duration and action load · Current EP001 scene-blocking example
06
Verified material
Why sound can drop out in an exported film
A v0.9.2 fix and our bounded synthetic-tone check separate document checks, export success and audio continuity.
On the morning of October 21, we verified that ZenStory had formally released v0.9.2 at 03:23 Beijing time. Its author documents a viewing-stage problem: even after sample rates and channel layouts match, concatenating separately encoded AAC segments can leave brief dropouts at cuts. The fix note reports about 32 milliseconds and says the existing verify measurements do not test this property. Correct subtitles, file duration and a successful export do not establish continuous dialogue or singing across an edit.
The source keeps the picture stream-copy path, but decodes each sound segment to PCM, pads or trims it to that segment’s actual picture span, joins the pieces and encodes AAC once. This targets gaps introduced by segmented encoding; it does not correct words, inconsistent voices or lip sync. For a maker, the practical check is to follow a sound that continues across shots and replay both sides of the cut in the actual delivery file. An audio track’s presence is only the start of that check.
We reproduced the author’s bounded regression setup: two one-second gray videos at 24 fps with a 440 Hz synthetic tone, 32 kHz mono audio, requesting a 0.9-second cut from each. We called the original pre-fix and v0.9.2 editing scripts, then measured peaks in five-millisecond windows of the decoded waveform. The pre-fix output contained a dip below one percent of the overall peak; the fixed output passed the threshold used in the author’s continuity test. This reproduces one synthetic signal and editing path. We did not rerender either sample film or audition speech, and a passing run does not establish film quality, lip sync or correctness for every source combination.
Documented process
Check beyond the presence of an audio track
Original-script before/after check using the same synthetic 440 Hz signal; not a film-quality test.
Hold input and cuts constant
Two one-second gray clips, 24 fps, 32 kHz mono; each edit requests 0.9 seconds, with actual spans aligned to the script’s picture frames.
Inspect test inputsMeasure the failure
The pre-fix script yields a minimum five-millisecond peak of 18 versus an overall maximum of 7509, about 0.24%, below the original 50% regression threshold. This compares waveform amplitude, not quality scores.
Inspect the pre-fix scriptKeep the check bounded
Using the same method, v0.9.2 yields 3908/7380, about 52.95%, passing the same threshold. This does not establish speech quality, cross-shot sync or a repaired earlier film.
Inspect the current render path
Evidence limitOne gray-video and synthetic-tone reproduction. Inputs, original-script commits, ffmpeg version and raw measurements are retained in BitShovel’s editorial receipt. No model or paid service was called.
Sources for this section: Drama Skills v0.9.2 formal release · Cut-point dropout and fix decision · Original synthetic-tone edit regression · v0.9.2 editing and render source
07
Our analysis
Fight scenes break down by rounds; QC stops blocking delivery
v0.10.0 and the November 2 v0.10.1 read separately: round-based breakdown and impact-selling are now storyboard rules, and the new review criteria send single-frame glitches and slight lip-sync drift to editing by default. In the authors' synthetic case only 1 of 12 segments still needs regeneration; BitShovel has not rerun any comparison.
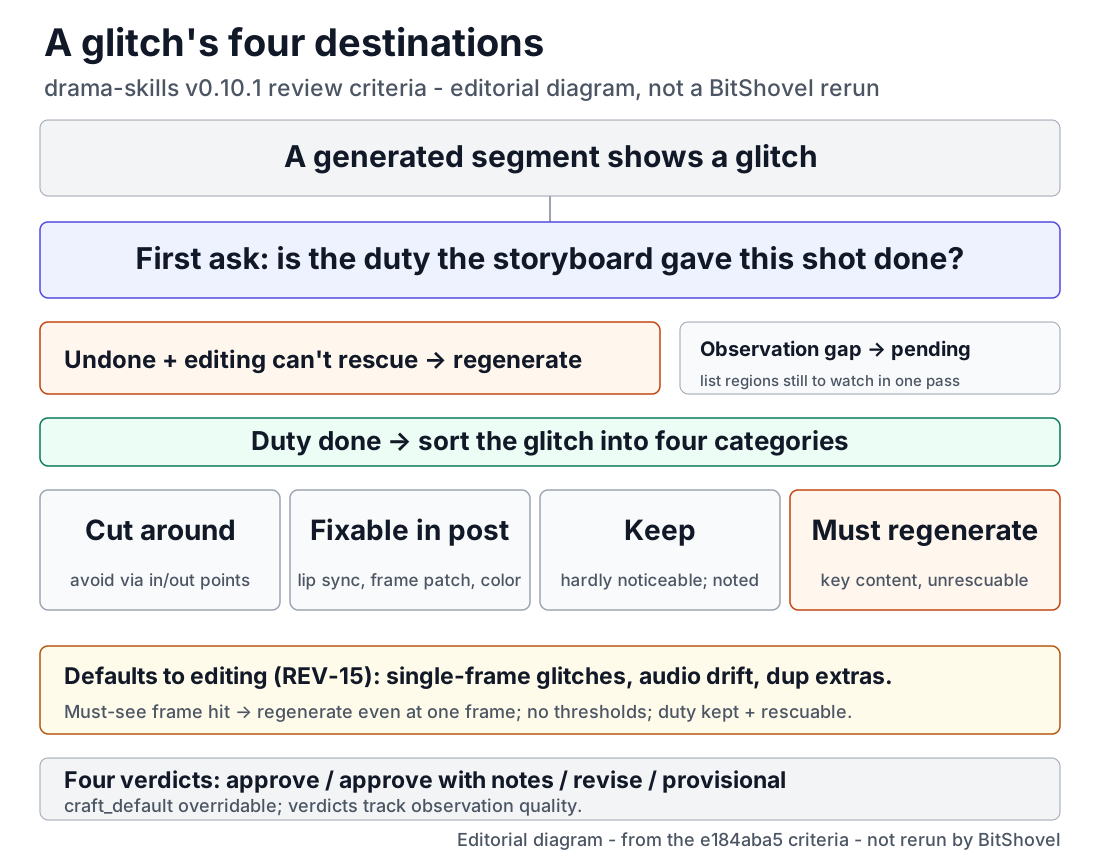
ZenStory's drama-skills formally shipped v0.10.0 on October 30 at 12:11 Beijing time, writing the fight-scene breakdown into storyboard rules, and v0.10.1 on November 2 at 14:24, aimed at what creators reported as "stuck at QC with no film out". Across this case a clear line runs: the checker chapter read what got missed and how the checker caught it; the blocking chapter read fixing geography before describing shots; the cut-point chapter read why export success does not equal continuous sound. This chapter reads the next layer: with no review criteria, sub-second glitches were all sent to regeneration; with criteria landed, the same synthetic case's 12 segments leave only one. BitShovel read the official documents and decision notes at fixed commit e184aba5 and did not call any generation service to rerun the comparisons.
The v0.10.0 fight method starts from a duration conflict: a single round usually lasts one or two seconds on screen, while the target model's shortest native clip is longer. First write the exchange ledger: each round gets three cells — the initiation (who, which hand or foot, holding what, from which side, written against fixed blocking anchors rather than screen-left/right), the response (dodge, block, catch, counter, or taking the hit), and the outcome (distance, orientation, who controls the weapon, injuries and stamina, and who has initiative next). Every round must change at least one outcome; two rounds with unchanged outcomes read as repetition, so go back to the script for what this round actually changed. Three ways to break down a round: the multi-shot container is the default — one round becomes "medium shot of the wind-up → close-up of the impact → medium shot of the aftermath" inside one generation, with editing tight-cutting at the generated cut points and keeping only a short span around the fist in the impact close-up; generating each beat as its own clip and letting every clip stop at minimum length cannot produce this rhythm. One-clip rounds run initiation, response and outcome as the shot's single continuous action, but words like "fast" or "in one fluid motion" cannot pull the action back to real speed — the model stretches however long a clip you give it, so pauses appear mid-round. Dedicated shots go only to information a wide shot cannot carry: a disarming, the decisive blow, or a reaction that changes the next choice. Intensity tiers are a taste option: restrained-realistic, commercial-boosted or surreal are the maker's choice, and injuries scale with that choice and the platform's content policy — not padded into the storyboard.
Selling an impact starts by classifying it. Misses, blocks, dodges, wrist catches and weapons striking the environment are exactly what the audience wants to read: a stable side or angled medium frame keeps the swing, the dodge and the result in one view; the author notes a weapon smashing the environment (sparks, splashes, dents) is easier to generate and conveys force better than a hit on a body. The true hit on a face or body is hardest to read and easiest to distort: two moving bodies meet at a contact point. Believing the hit relies on three things, not on clarifying the exact frame where the fist meets the face: in a continuous shot, the camera stays on the same side of the axis, moving behind the striker's shoulder so the fist or foot travels toward or away from the lens and the contact point hides behind a foreground arm or shoulder; in multi-shot coverage, an impact close-up where the fist enters from off-screen, with only the receiver framed, so the contact point can show — this shot is where "punchy impact" comes from, provided editing keeps it short; and the receiver's reaction must match the force direction — head snapping along it, feet stumbling back, hand covering the spot — plus a thud or a knocked-askew object. Contact shots stay flagged high-risk with a downgrade ready (cut one frame before the fist lands, or cut straight to the reaction). With multiple opponents, every opponent holds a fixed bearing; only one strikes per round while the others wait visibly; when the protagonist turns to face another, re-establish who is where with a wide before the next round. In 9:16 the horizontal band is narrow, so horizontal swings and side kicks easily exit frame; lay the fight along depth or a diagonal, and raised weapons and high kicks need vertical headroom.
v0.10.1 fixes four dead ends. 1) No outlet for continuation segments: the built-in producer's source picker cannot bind continuation video, so from the second segment on every link reads "awaiting continuation, not submittable" — while rules bar switching to text-to-video or omitting the picker, and the only exit (the maker asking for independent regeneration) is never asked for. Now the flow asks once: generate each segment independently from its confirmed start frame, or submit later segments in your own tool; asked once, never again. 2) One image written into two slots: documentation taught splitting one image into two slots, the checker passed it, yet production requires unique binding paths — the maker wrote it per the docs, the checker approved, production rejected, and after being returned the maker wrote it back the same way; now one image occupies one slot, the main role under "用途/purpose", the second role under "控制/control". 3) No loudness tolerance: -16.4 against a -16 target counted as failing, so the agent rerendered endlessly; the default tolerance is now ±1 LU around target with true peak at or below the declared ceiling (-1.5 dBTP when none is declared), a single external pass that still misses is reported outright instead of looping, and makers can rewrite the tolerance in the edit sheet's loudness-delivery line. 4) No review criteria for generated media: the review scope listed production outputs and the final cut, but the review skill shipped no reference material for them, and REV-11 forced every glitch into a "to fix" item.
The new REV-15 criteria ask segment by segment whether the duty the storyboard assigned this shot got done: done / not done / unknown — segments whose duty region the observations did not cover are recorded as pending observation, not as defects; glitches then sort into four categories: cut around (avoid via in/out points), fixable in post (nudge audio to lip sync, patch a frame, color, remove small background objects), keep (hardly noticeable in normal playback, noted for editing without touching the material), or must regenerate (no usable span, no other shot can carry the information, post cannot produce it either). There are no frame or second thresholds; the criterion is whether the shot's duty survived and whether editing can rescue it. The default classification (craft_default) sends single-frame or sub-second glitches, slight audio offsets and briefly duplicated background extras to editing without blocking delivery; but if the glitch lands on the one frame the audience must see — say the key prop's first appearance is corrupted — even one frame forces regeneration. Makers can override the default, for example demanding zero glitches for a key shot, with the change written into the review record. The synthetic case shows the gap: 12 generated segments — 8 clean, 3 with one small glitch each (a one-frame tear, dialogue 0.3 s late, background extras duplicated for 0.5 s), 1 missing its key prop entirely; under the old rules all 4 were sent to regeneration plus 3 prompt revisions and a blanket REVISE; under the new criteria only the missing-key-prop segment regenerates, and the 3 small-glitch segments go into the editing notes. The author states two limits: the full-episode review was self-checked on one synthetic case only, guide and review came from the same agent, and an independent reviewer must still validate it in real runs.
On November 1 the makers ran nine generation comparisons on Seedance 2.5 and H3, each first generating a baseline with the current wording; clips were frame-sampled, shuffled and label-hidden, then blind-judged by one model, with NCC and cut-point metrics alongside; the full numbers live in evaluations/model-behavior-probes.md. Four wordings won and landed in the skills: Seedance 2.5 multi-shot containers can attach one confirmed keyframe per shot, steadier composition and characters across later shots (recorded: 2 of 3 blind evaluations matched the ceiling of generating separately and editing; the cost is that one failure redoes the whole container). MiniMax H3 close-ups and talking shots without a start frame anchoring the face, where the identity slot holds only a full-body sheet, can attach a same-Look head-shoulder face board for a truer face; the face board and body sheet must come from the same confirmed character image; the maker notes the "aging" of night close-ups is not solved by the face board, which cannot replace comparing faces after generation. "Extend" only appends; "before" in prose does not work; to prepend to an accepted clip, use first/last-frame generation with the original first frame as the new segment's last frame (recorded blind score 4/5; a post-hoc "trimmed extend" scored 3/3 blind at 5/5 but sits outside the comparison design). Blocking anchors must be fixed objects visible in the scene reference image; naming a large object absent from the image makes the model add a different one each run — recorded three runs adding three different bookshelves, twice blocking the sofa already in the image. The other five groups only add rows to the observation record: two groups (three people, one speaker; in-picture signage) had baselines already at the ceiling; three groups (idle head-tail time in fight scenes, waiting opponents in a siege, motion reference for rhythm only) underperformed current wording. Limits per the maker: 3 runs per group, one scene, blind judgment by one model — "better in this group", not a success rate.
Editing's verify gains "cut-point level jumps": it takes 0.4 s on each side of a cut (with a 0.03 s guard) for RMS levels; since a downmix would cancel inverted stereo into silence, channels are measured separately with the louder channel winning; the floor is -70 dBFS. Measured across six assembled demo films: 31 cuts, 13 with pre/post changes over 6 dB, 9 over 10 dB — deliberate impacts and seams are mixed together, and the listener does not know which cuts to audition first. The threshold is 10 dB (roughly a doubling of loudness), listing about a third of cuts; it is a hint only and does not affect delivery — the maker states verify only measures and does not conclude, and the threshold only decides which cuts get listed. Known limits: RMS is unweighted, so low-frequency content inflates levels; ramps crossing a cut may under-report; segments shorter than about 0.13 s are not compared. Joined with the cut-point chapter this completes a line: structural checks, export success, continuous sound (v0.9.2 removed the ~30 ms cut dropout) and "where to listen back" (v0.10.1 lists cuts over 10 dB) are four different things.
 View full image ↗
- Read the v0.10.1 release notes
- Read the v0.10.0 release notes
- Read the fight-scene storyboard rules
- Read the generated-media review criteria
- Nine-comparison decision note
- QC dead-ends fix note
Sources for this section: Drama Skills v0.10.0 formal release · Drama Skills v0.10.1 formal release · Fight-scene storyboard rules · Generated-media review criteria · QC dead-ends fix decision note · Nine-comparison landing decision note · verify lists cut-point level jumps
08
Our analysis
Benchmark breakdown: measure the leaders, then reset your own defaults
v0.10.2 adds a benchmark-breakdown skill: a script measures episode length, cut points and shot length, with dialogue numbers when subtitles or transcripts exist. Measured across 9 serialized anime dramas on short-drama apps, the default anime-drama pacing start moved from 3.0 to 2.6 seconds. Gap tables go to the responsible skill; output verification runs two versions with the same model, at least twice each, blind-judged. BitShovel read the skill documents at fixed tag v0.10.2; it measured no benchmark dramas and called no generation service.
ZenStory's drama-skills shipped v0.10.2 at 12:01 Beijing time on November 4 (the changelog is dated November 3), adding the benchmark-breakdown skill. The case's line of insight moves one layer further: the checker chapter read what got missed and how the checker caught it; the staging chapter read fixing blocking before writing shots; the cut-point chapter read why export success does not equal continuous sound; the fight/QC chapter read how to break down and what passes QC. This chapter reads the third step — learning from benchmarks: measure others' finished films into recomputable numbers, then compare with your own. BitShovel read the changelog, SKILL.md and four reference documents at fixed tag v0.10.2 (release notes c8f90a79); it measured no benchmark dramas and called no generation service.
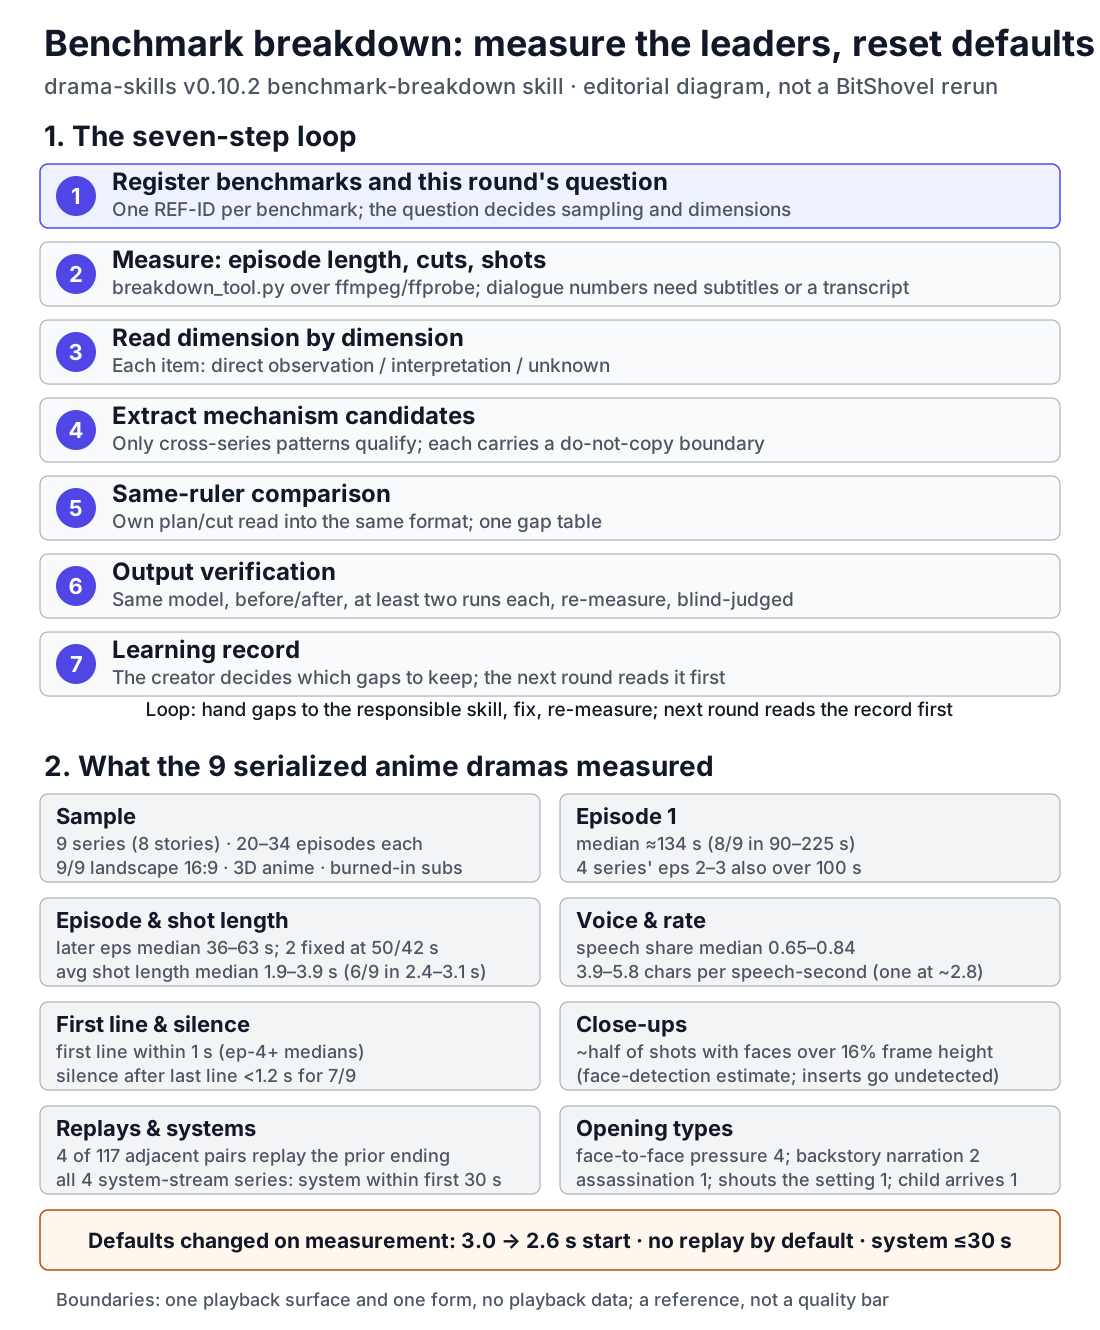
Registering a benchmark starts with this round's question — the question decides which episodes to sample and which dimensions to read. Each benchmark gets a REF-ID with source, permitted use, playback surface and production form; original films, transcripts and contact sheets stay in the benchmark input folder, never in deliverables, examples or any file that becomes public, and reports carry no benchmark title, character names, dialogue or distinctive plot devices. Measurement runs breakdown_tool.py: measure uses ffmpeg and ffprobe for per-episode duration, cut points and shot lengths, plus a contact sheet of the midpoint frame per detected shot; attach subtitles or a timed transcript and the dialogue numbers follow (speech share, speech rate, first-line timing, silence after the last line); profile separates opening episodes from later ones and reports two series-level facts: whether later episodes approach fixed length, and how often the next episode opens by replaying the previous ending. The project's own plan reads script and storyboard into a same-format measurement file, the finished cut uses the same measure, and both sit beside the benchmarks in one gap table. Each gap first asks the creator whether it was intentional; unintentional gaps go to the responsible skill to fix; after the fix, take a scene that represents the gap, generate before/after versions with the same model (same aspect ratio unless aspect is what you changed), at least two runs per version watching stability rather than picking the best take, re-measure with the same ruler, and blind-judge the picture with version labels removed; results go into the learning record, which the next round reads first.
The reference table is itself a measurement: 9 serialized 3D-anime-style AI dramas on short-drama apps, 20–34 episodes each, speech-recognition transcripts, cut-point threshold 0.28; two of the 9 are two versions of one story, so 8 stories, and the table counts by series. 9/9 landscape 16:9 with burned-in bottom-center subtitles. Episode 1 median about 134 s (8/9 within 90–225 s); later episodes per-series median 36–63 s, with 2 series fixed-length from episode 4 (50 s and 42 s); average shot length per-series median 1.9–3.9 s, 6/9 in 2.4–3.1 s, fight and FX segments down to under 1 s; speech share median 0.65–0.84; speech rate median 3.9–5.8 characters per speech-second, one costume-intrigue drama slower at about 2.8. First line within 1 s for every ep-4+ per-series median; silence after the last line under 1.2 s for 7/9; 4 of 117 adjacent episode pairs replay the previous ending. Close-ups were estimated separately on episodes 1–3 and 10: shots with a detected face taller than 16% of frame height are about half of shots (per-series median); inserts and profile views go undetected, so the real share is higher. Episode-1 openings: face-to-face pressure 4 series, first-person narration compressing backstory or previewing the outcome 2, narration plus an in-progress assassination 1, the protagonist shouting the setting 1, an unfamiliar child arriving 1. In all 4 system-stream series (3 stories), the system speaks or is named within the first 30 seconds of episode 1.
On this evidence, v0.10.2 changes two defaults and a batch of writing estimates, with the upgrade note stating no migration is needed. Pacing profile: the anime-drama average-shot-length start moves from 3.0 to 2.6 seconds, and the next episode no longer replays the previous ending by default; accepted profiles are unaffected — adopting the new start means re-proposing and accepting the pacing profile once more. Story development: episode 1 can get its own longer target duration in the episode map, and system-stream works are advised to bring the system in within the first 30 seconds of episode 1 — advice taken straight from the measurement. Writing estimates add speech_seconds and speech_share (seconds and share of estimated duration with someone speaking): when the anime-drama share sits clearly below the benchmark, the skill first hands speakable conflict to dialogue, then removes silent action that would be illegible after generation. Episodes with their own target duration get --target-seconds for per-episode comparison; system voice only the protagonist hears and inner voice are marked [VO] and count toward the narration share; broadcasts others can hear are [OS]; a lead character's first appearance can add a name plate written as [画面文字] 名条:…, overlaid in post.
The same measurement round also landed a text-to-video wording rule. With MiniMax H3 text-to-video for 2D animation, the prompt's body must open by naming the medium and stating it is not live action, repeated once per cut; per the maker's recorded tests, only with this phrasing did the 2D art style not drift to live-action humans. 3D anime cannot be held by text alone: the skill warns before you choose text-to-video and suggests a style-locked start frame at each segment's opening.
The reference table has explicit boundaries, stated right after the table: the sample covers one playback surface (short-drama apps, landscape 16:9) and one form (3D anime), with no vertical, live-action or 2D works and no playback data, so it cannot answer “which approach is more popular”; the numbers are a reference, not a quality bar, and do not transfer directly to other playback surfaces or forms. The numbers themselves have blind spots, with how to patch them documented: the cut-point threshold misses slow dissolves and counts flash frames, whip pans and particle FX as cuts; transcripts cannot separate dialogue, narration and system voice, and vocals inside the score may enter the dialogue numbers; a pure sound-effect or picture hook opening makes a late first line say nothing about the hook's timing; the close-up row is a face-detection estimate, not script output. Mechanism candidates and pacing values take effect only with creator acceptance — the skill does not set numbers for the maker. BitShovel read documents at a fixed tag; it measured no benchmark dramas and called no generation service.
 View full image ↗
- Read the v0.10.2 release notes
- Read the benchmark-breakdown skill document
- Read the measured reference table of the 9 dramas
Sources for this section: Drama Skills v0.10.2 formal release · Benchmark-breakdown skill document · Breakdown dimensions and the measured 9-drama reference table · Measuring and reading: sampling, transcripts and number blind spots · Gap comparison and output verification
09
Our analysis
Whole-episode reconstruction: from measured numbers to a generatable script
v0.11.0 lets benchmark breakdown reconstruct whole episodes: a verbatim script, cross-episode-consistent characters and scenes, per-shot storyboards and prompts; a 12-episode run reports a 0.34% character error rate (all intentional differences), and shipping one 13-shot episode over six revisions landed three crafts: a master room view, reference audio bound at generation, and cut wordings. BitShovel read the documents at fixed tag v0.11.0; it reconstructed no drama and shipped no film.
ZenStory's drama-skills shipped v0.11.0 at 16:38 Beijing time on November 6, taking benchmark breakdown from measuring numbers to reconstruction: a benchmark episode or run of episodes is rebuilt as a suite project — a verbatim script, cross-episode-consistent characters and scenes, one storyboard row per measured shot, and the matching image and video prompts, with episodes that join. The case's line of insight moves one layer further: the checker chapter read what got missed and how the checker caught it; the staging chapter read fixing blocking before writing shots; the cut-point chapter read why export success does not equal continuous sound; the fight/QC chapter read how to break down and what passes QC; the benchmark chapter read turning finished films into recomputable numbers. This chapter reads the fourth step — reconstruction: how a measured shot table becomes a whole-episode suite project that can be generated from, and which space, voice and cut crafts landed when the reconstruction was shipped. BitShovel read the changelog, reconstruct.md, the continuity decision note and the H3 wording doc at fixed tag v0.11.0 (source commit 372b62fb); it reconstructed no drama and called no generation service.
The reconstruction layer is a standalone suite project at 输入/对标/<REF-ID>/还原/, initialized before writing files, under its own episode number that other stages never read; permitted use study stays internal for mechanism distillation and comparison; owned or licensed with provenance may continue into generation; uploading the original film to an external model service requires consent recorded in the register, otherwise only local measurement runs and the viewing pass is skipped. The script does not watch film: the tested viewing channel is the Antigravity CLI with gemini-4-argon-high, a fresh empty directory per call — consecutive calls in one directory leak what was seen before into the next answer. Before trusting it, confirm it hears the audio track (transcribe a ten-second clip cropped to exclude the subtitle band verbatim); gemini-3.8-flash cannot receive audio and only reads frames, and the model's own claims about what it received are unreliable — the same model claimed per-second frames with no audio while actually hearing the track. Four steps: 1) measure — subtitle-sheet builds a calibration contact sheet from the frames richest in stroked glyphs across two or three episodes; set region and color first, then scan; audio gives voiced spans and loudness; subtitles stores a crop per line at about 0.1 s precision without reading characters (text is read from crops; crowd voices and panel system voices stay out of the results); shots cuts three frames per measured shot and lists in-shot candidate cuts. 2) One full-episode pass: dialogue, characters, scenes, props, on-screen text, SFX and score, beats, whether opening/ending break mid-sentence or mid-action, and render, color and light. 3) A per-shot pass: framing, angle, camera move, subject, blocking and gaze, action start and end states, expression, matched lines, transitions, with concrete head/tail frames — they are the keyframe-prompt base. 4) Alignment: line timing defers to subtitles (model times run 0.3–0.6 s early, originals kept); text cross-checked both ways (script written by ear, subtitle originals kept); cuts defer to measurement (model-reported cuts matching candidates confirmed by frames, mismatches go to a human — never auto-deleted or auto-accepted); attribution recomputed by intersecting line spans with shot spans, not the model's own labels; names only from on-screen or dialogue evidence — the model invents names for people who never appear.
reconstruct.md devotes a section to the evidence: on November 4, 2026, a 3D-anime system-stream drama, 16:9 with burned-in subtitles, 160 episodes, the first three 112–148 s and then a fixed 50.03 s each; the first 12 episodes were reconstructed, 854 s in total. 371 lines of dialogue: frame-sampled 46 lines / 388 characters, 2 wrong, a 0.52% character error rate; full comparison over 350 lines / 2927 characters gives 0.34% — the gap is entirely the script correcting subtitle typos by ear, an intentional difference. Two episodes sampled at 0.5 s counting subtitle events: zero missed lines. Visual hallucination sampled 16 shots: 12 right, 3 partial (action direction or end state flipped), 1 wrong — the first 0.37 s of an episode's first shot, actually the previous episode's tail continuing, was read as a person in a reverse angle. The 0.28 threshold missed 31 in-shot cuts in one episode, up to 8 per shot; candidate cuts (0.1 threshold) listed 33 segments covering 27 of them; the misses were soft cuts and a fast-cut cluster. Six episodes cross-checked: subtitle-scan line starts vs. manually verified starts all within 0.25 s (one at 0.3 s); the mismatches were panel system voices and crowd voices, plus one subtitle flicker split into 4 segments. Names and on-screen text each had a failure: the model invented a name for a father with no on-screen or dialogue evidence; two on-screen clock texts were taken for dialogue, audio shows score noise, reclassified as on-screen text. 11 seams: 3 broke mid-sentence, 5 open by replaying the previous ending. The maker states the cost boundary: 12 episodes in parallel ran about 110 minutes wall clock with two Argon calls per episode plus rework listening; one episode's whole-episode call was interrupted midway, and on retry the personal quota was exhausted (429, reset in about 6 days), so that episode's script was patched from subtitle crops with no per-shot description.
Subtitle-region calibration has its own run: 22 landscape 3D-anime series each contributed one episode, plus 7 synthetic subtitle styles composited from 4 of them (original subs cropped out), each style 21–26 lines with known timings. Default region and color across the 22 series: 1 series caught no lines (subtitles at 0.80–0.86 frame height), 1 is thin-stroke (voiced_shown_share 0.29); after re-boxing, the first rose from 0 to 0.60, and the rest sat at 0.49–0.83. On synthetic samples, counting lines caught within 0.25 s per style at 95 lines each: white with stroke 95, white on a semi-transparent box 92, vertical subs at 0.88 height 95; vertical subs at 0.75 height caught 0 by default and 95 after re-boxing; yellow text without --color caught 0 and 95 with --color, yellow with box 92; median start-point error within 0.02 s, false positives within 1 segment. Thin strokes stay the weak spot: 80 of 95 lines, with 35 lines split into fragments. Set values go into the register for the whole series; when the first episode's title cards differ, episode 1 is calibrated separately.
The continuity crafts for shipping a reconstruction come from the November 6 decision note: one 45-second, 13-shot episode went through six revisions from keyframes → H3 first-frame image-to-video → edit, and the viewer kept flagging three classes. Space: the counter hugs a tiled wall, then a floor-to-ceiling window; the fridge and window swap places; a second device appears from nowhere; distance to the counter drifts — there was never a “true” room: each camera's location plate was generated independently, every keyframe was repainted from plate-plus-text, the previous keyframe as reference fails to carry distance, blocking named only a side (never a distance), and space that was already impossible in the original got copied in. The fix: for one location shot from several directions, produce one master view first and derive the front and reverse direction plates from it, checking each against the master; a keyframe's space binds exactly one plate on the shot's side; blocking is written in body distances (“right against the outside of the counter, the edge at waist height”); non-walking characters lock to their anchor's side; and space that is impossible in the original is not carried into generation. Voice: with prose-only voice description, H3-style joint audio-video generation re-picks a voice per clip — the same character changes voice across shots; a separate synthetic VO can align lips only whole-line, judged worse than the model's own voice. The fix: when a character speaks in two or more shots, bind reference audio at generation (full-reference; the start frame goes in as a reference image); voice drift found in editing goes back to regeneration, not post; the maker tried vocal separation plus zero-shot voice conversion — similarity to the reference voice rose from 0.19–0.59 to 0.75–0.87, but quality and emotion would not survive conversion, so it was not adopted. Cuts: cutting 0.3 s after a line into a shot with a very different framing and blocking reads as hard; wanting to cut on the turn, H3 first-frame mode ignores turn direction in prompts (6/6, 3/3 reversed; all 9 candidates reversed) — cut before the turn starts instead; leave reaction time after lines; use start-frame shots from frame one without speeding up; review splices each segment's head/tail frames in shot order into one image to check spatial continuity. The cut runs about 13 seconds longer than the original: speech starts 1.3–2.4 s late plus reaction beats after lines — acceptance checks beats, lines and per-shot duties, not total seconds; when a sound-capable model reviews the film, hand it the reconstruction's storyboard too, or it will score the original's own grammar as defects (unmoving lips during inner monologue, calling out while facing away).
This chapter keeps the three evidence layers separate and states the boundaries. Upgrade note: previously registered benchmarks need two additions before reconstruction — permitted use (study, owned, licensed) and whether uploading the original film to external model services is allowed; without the upload consent, only local measurement runs. The maker states the boundaries of each layer: the 12-episode reconstruction and 22-series subtitle calibration are two different sets of material, the continuity numbers come from one 13-shot episode on one execution channel (H3 first-frame image-to-video), and numbers like late speech onset and ignored turn direction must be re-measured after a model version change; in the fidelity table, “storyboards copied verbatim from measured cuts necessarily match shot counts, total length and median shot length — that is not evidence”. BitShovel's boundary: it reconstructed no drama, shipped no film, and called neither Argon nor H3; every number and craft here is the maker's own measurement. Read together with the previous chapter, one line completes: measuring answers “where others got to” (the 9-series reference table), reconstruction answers “how exactly it was made” (verbatim script, per-shot storyboard, per-shot prompts), and the continuity crafts answer “where you will stumble when you try it”. The three measured runs (12 episodes, 22 series, one 13-shot episode) are three evidence layers of one pipeline, none standing in for another.
 View full image ↗
- Read the v0.11.0 release notes
- Read the whole-episode reconstruction method (reconstruct.md)
- Read the continuity learnings note (space, voice, cuts)
- Read the H3 prompt dialect (turn direction, speech onset, voice binding)
Sources for this section: Drama Skills v0.11.0 formal release · Whole-episode reconstruction (reconstruct.md) · Continuity learnings note (space, voice, cuts) · H3 prompt dialect (v0.11.0)
10
Our analysis
What transfers and what remains unknown
The open files help study production; business results need separate evidence.
The repository publishes its code and workflow under MIT, making it useful for studying an inspectable production process. Image, video and voice services may charge and carry separate terms, as may source material and generated media. The repository license does not override those rights.
A manageable trial is one rights-cleared scene: record characters, place and props, make a few shots and keep each input, candidate and rejection reason. Plan distribution and audience testing as a separate phase; completion alone does not show that a work can sell.
Sources for this section: ZenStory drama-skills repository · drama-skills MIT license
A BitShovel exercise · not the maker’s tutorial
Make a traceable sample from your own story
Use ZenStory's documented links from script to visual plan, storyboard, prompt and edit to try a 20–30-second scene. This is a BitShovel exercise; your story determines the shots and delivery values.
Before you begin
- Use an original or clearly licensed scene; inspect the original sample, real outputs and repository license.
- Record service terms, budget and vertical delivery requirements; the repository's MIT license does not grant source or service rights.
Write one visible conflict
Reduce the scene to a character goal, obstacle, turn and no more than two essential lines; mark actions the viewer must see.
- Keep
- A one-page script and duration target
- Check
- Identify the action that carries the conflict without relying on voiceover or lore.
Lock continuity facts
Make a compact visual sheet for wardrobe, setting and props, with a source or original-design note for each.
- Keep
- A character, place and prop sheet
- Check
- The same people and props remain recognizable, and references stay within your rights.
Trace shots back to the script
Number three to five shots, recording start and end frames, action, duration and visual references before drafting video inputs.
- Keep
- Numbered storyboard and shot-input sheet
- Check
- Every character has a visual basis, and durations, props and actions agree across storyboard and inputs.
Generate and separate two kinds of error
Keep at least two candidates and rejection reasons per shot; check missing references and mismatched durations in documents, then watch for expression, action and continuity faults.
- Keep
- Candidate and error log
- Check
- Passing document checks does not make footage usable; the selected take must serve the shot's story role.
Edit and check the actual media
Record each clip's in and out points and why, time captions to actual speech, check format and loudness, then show it to an unfamiliar viewer.
- Keep
- A short cut, edit sheet and delivery checks
- Check
- Captions stay within the cut, output matches the chosen format, dialogue is audible and viewers can recount the turn.
Make one final choice: If identity or props drift or the turn remains unclear, revise the visual sheet or storyboard. If the budget is spent, stop at the sample; completion is no claim of reach or revenue.
ZenStory's published example and run log are references. BitShovel designed these five steps, candidate count and checks; deliberately damaged checker examples are not production failures.
Sources and limits
Where the material comes from
- Drama Skills v0.9.2 formal releaseFormal project releasePublished Checked
Originally published October 20 at 19:23:51 UTC, October 21 at 03:23 Beijing time; source fdb7b7c58017.
- Cut-point dropout and fix decisionCreator failure and fix notePublished Checked
The note originated September 28; the October 20 commit adds the v0.9.2 dropout finding. Its filename is not the new fix’s publication date.
- Original synthetic-tone edit regressionPinned original test sourcePublished Checked
Two 440 Hz clips and a five-millisecond peak threshold; BitShovel reproduces it with the pre-fix and current scripts.
- v0.9.2 editing and render sourcePinned original implementationPublished Checked
Copies the picture stream and aligns PCM to picture spans before a single AAC encode; no film regeneration or lip-sync repair.
- September 27: the opening sample replaces the earlier clipDated creator commit and README diffPublished Checked
The 24-second clip is replaced with a 68-second opening. Twenty shots and approximately RMB40 are creator statements, not total project cost.
- Drama Skills v0.9.1 formal releaseProject release recordPublished Checked
October 20 guidance on scene blocking, shot load, references and endpoint frames.
- Scene blocking and camera-relative compositionCreator method documentPublished Checked
Record persistent spatial relations, then translate them into foreground, background, screen sides and gaze targets for the current camera.
- Model-behavior observations and execution limitsCreator small-sample report, not a BitShovel testPublished Checked
October 20 Seedance2.0, 480P, 9:16, five-second probes. Raw media is outside the public repository; this is neither a playable A/B nor a reliable success-rate estimate.
- Shot duration and action loadCreator guidance derived from reported probesPublished Checked
Allocate duration according to whether the audience can read each action, rather than imposing a fixed action count.
- Current EP001 scene-blocking exampleCurrent document example, not a shot-by-shot production log for the 68-second filmPublished Checked
Adds blocking for two scenes; explicitly says usable images are unavailable and text-to-video was chosen, rather than presenting generated frames.
- ZenStory drama-skills repositoryCreator's work and projectChecked
24-second sample, end-to-end workflow, installation and project notes.
- Documented real outputsCreator process recordsChecked
Script, visual plan, storyboard and prompt for one shot; actual errors and editing choices.
- Open EP001 exampleOriginal filesChecked
Traceable example script, visual plan and shot files.
- Original sample run logOriginal file in a historical commitChecked
Production, checks and actual errors; the current real-outputs document summarizes it.
- Original sample edit sheetOriginal file in a historical commitChecked
In and out points and reasons for eight clips; the current real-outputs document summarizes it.
- drama-skills MIT licenseRepository licenseChecked
Project file license; external services and source rights require separate checks.
- Drama Skills v0.10.0 formal releaseFormal project releasePublished Checked
Shipped October 30, 12:11 Beijing time; round-based fight breakdown and related storyboard methods.
- Drama Skills v0.10.1 formal releaseFormal project releasePublished Checked
Shipped November 2, 14:24 Beijing time; QC no longer blocking delivery and the review criteria.
- Fight-scene storyboard rulesCreator method documentPublished Checked
Exchange ledger, round-based breakdown and impact-selling rules (craft_default, overridable).
- Generated-media review criteriaCreator review criteria documentPublished Checked
Judge shot duty first, then four categories; single-frame glitches default to editing; a glitch on a must-see frame regenerates even at one frame.
- QC dead-ends fix decision noteCreator failure and fix decision notePublished Checked
Four QC dead ends (continuation, dual slots, loudness tolerance, missing criteria) plus the synthetic-case before/after.
- Nine-comparison landing decision noteCreator probe and landing decision notePublished Checked
Nine comparisons, blind-judgment method, four landed wordings and five probe-only rows; limits of 3 runs per group on one scene.
- verify lists cut-point level jumpsCreator decision notePublished Checked
0.4 s RMS windows around cuts, 10 dB about doubling loudness, measure-only; measured on 31 cuts across six demo films.
- Drama Skills v0.10.2 formal releaseFormal project releasePublished Checked
Shipped November 4, 12:01 Beijing time; the benchmark-breakdown skill and measurement-calibrated defaults.
- Drama Skills v0.11.0 formal releaseFormal project releasePublished Checked
Shipped 2026-11-06T08:38:59Z (16:38 Beijing), source commit 372b62fb; upgrade note: registered benchmarks need permitted-use and upload-consent fields.
- Whole-episode reconstruction (reconstruct.md)Pinned original documentPublished Checked
Viewing channel Antigravity CLI + gemini-4-argon-high; line timing defers to subtitles (model times 0.3–0.6 s early); names need on-screen/dialogue evidence; measured runs for the 12-episode reconstruction and 22-series calibration.
- Continuity learnings note (space, voice, cuts)Dated maker implementation notePublished Checked
One 45 s / 13-shot episode over six revisions landed three crafts; zero-shot voice conversion (0.19–0.59 to 0.75–0.87) not adopted; evidence is one episode on one channel.
- H3 prompt dialect (v0.11.0)Pinned original documentChecked
First-frame mode ignores turn direction (6/6, 3/3 reversed); speech onset 1.3–2.4 s late; two-character names unstable; bind reference audio when speaking across 2+ shots.
- Benchmark-breakdown skill documentCreator method documentPublished Checked
The seven-step workflow and material boundaries: no benchmark titles, dialogue or plot devices in reports; original films stay out of deliverables.
- Breakdown dimensions and the measured 9-drama reference tableCreator method document with the measured reference tablePublished Checked
Measured across 9 serialized dramas on short-drama apps (8 stories, counted by series); dimensions recorded as observation/interpretation/unknown.
- Measuring and reading: sampling, transcripts and number blind spotsCreator method documentPublished Checked
Sampling rules and transcript sources by availability: subtitles, local transcripts, or left blank; blind spots documented item by item.
- Gap comparison and output verificationCreator method documentPublished Checked
Same-ruler comparison; gaps go to the responsible skill; verification runs before/after with the same model, at least twice each, re-measured and blind-judged.