Models and integration · Another choice for local coding
Flint: what does a coding agent need to work on your laptop?
Recursive releases a 39.8B-parameter coding model and a local engine. It offers another way to keep code on your device; short-context generation, long-task success and hardware requirements need separate scrutiny.
Recursive released Flint and its local engine on October 21. rec currently supports M4 Pro, M5 Pro or M5 Max with at least 48GB unified memory and around 30GB disk; other runtimes and precision recipes need separate checks. Figures below are publisher results. We did not install the engine or run coding tasks.
Keeping code on your machine still takes more than a model
Recursive positions Flint as a model for local coding agents: inspecting repositories, investigating bugs, implementing features and writing tests. It provides text reasoning and multi-turn tool calls, activating roughly 2.5B of its 39.8B parameters per token. That describes selected computation, not a 2.5B-sized memory footprint or proof of a completed engineering task.
The accompanying rec engine serves local inference, while coding harnesses such as Pi or OpenCode connect files and commands. These components can keep code processing local; whether any data leaves still depends on connected tools, network requests and configuration. This is a choice to investigate for local workflows, rather than a ready assistant on every laptop.
Sources and further reading
- Recursive: introducing FlintPublisher article · October 21Model aims, speed charts, evaluation settings and the claimed role of Eureka Machine in development.
- Flint model card and complete evaluation chartOfficial model card · pinned revision39.8B total and roughly 2.5B active parameters; text input/output, a 262,144-token configuration, BF16 serving and evaluation limits.
- rec: supported hardware and single-session conditionsOfficial repository README · pinned commitM4 Pro / M5 Pro / M5 Max, at least 48GB unified memory and about 30GB disk; distinct from model capability.
- Runtime entry and coding-harness connectionsOfficial integration documentationChoose the checkpoint, runtime and hardware together; we did not execute the installer.
Read the task and setup before the score
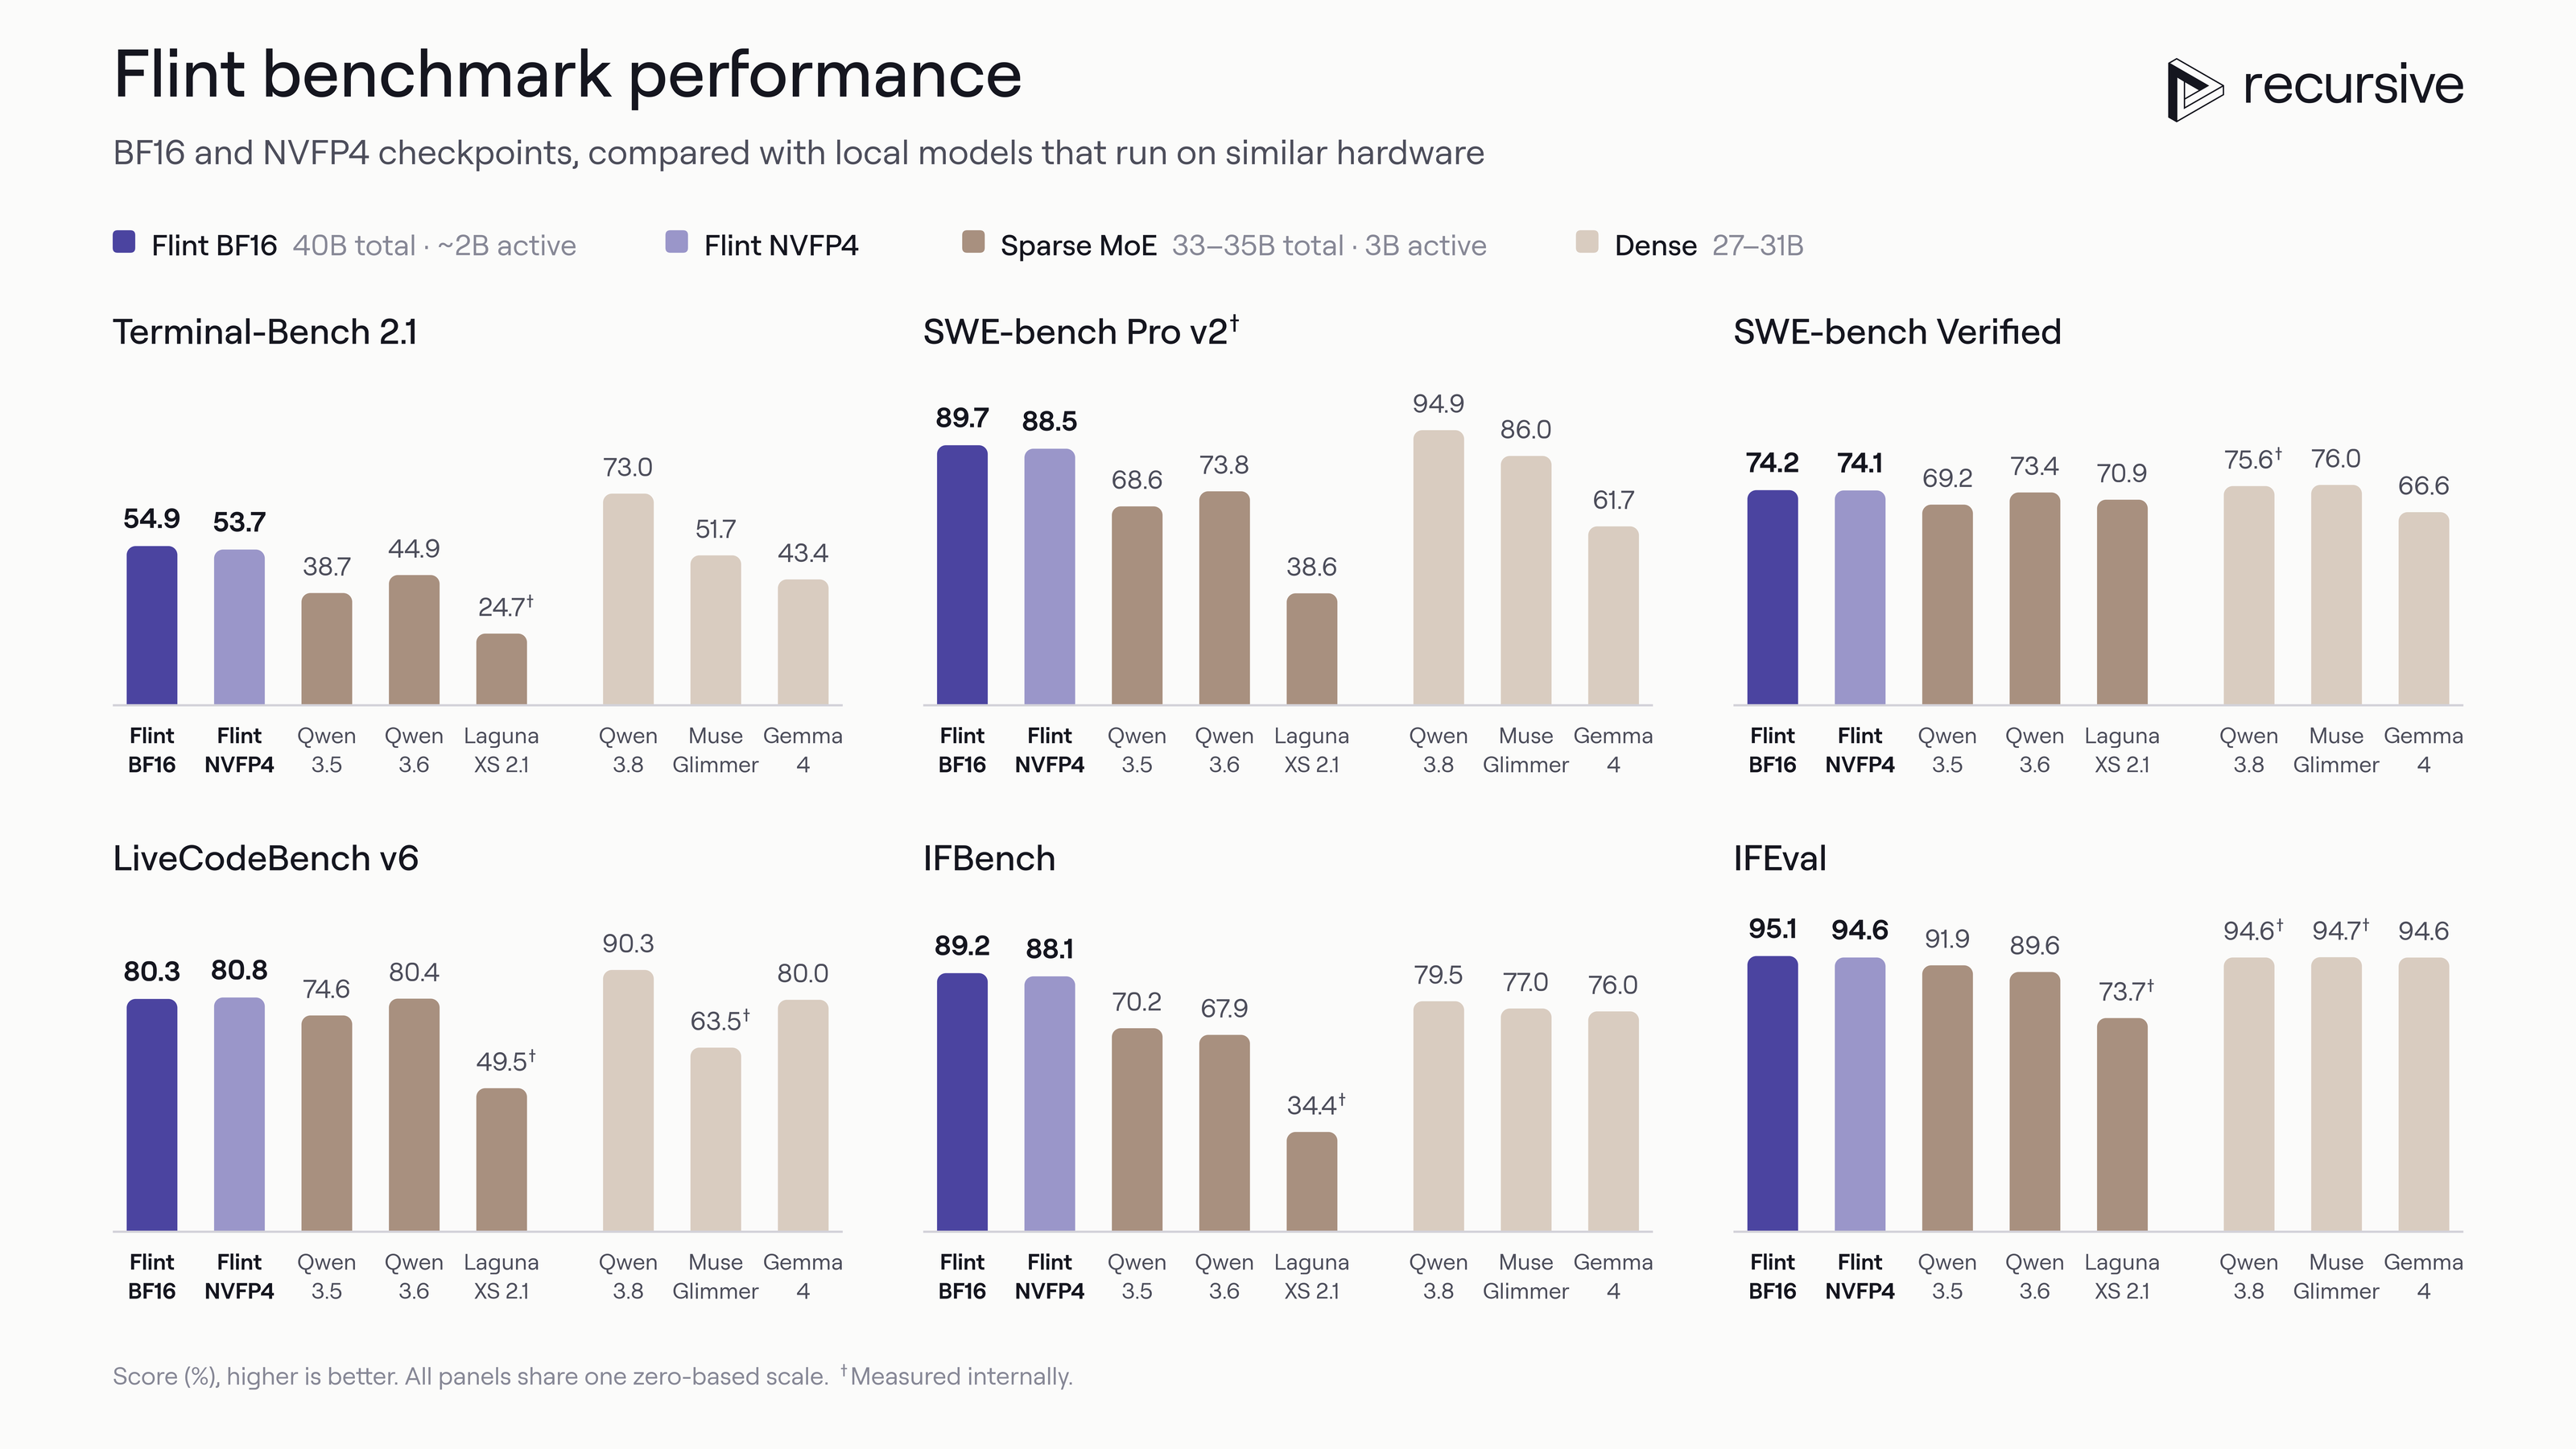
Publisher-reported BF16 results are 54.9% on Terminal-Bench 2.1, 89.7% on SWE-bench Pro v2 and 74.2% on SWE-bench Verified. These describe prescribed terminal and code-repair tasks, rather than an ability to deliver 89.7% of real projects. Larger dense models remain higher on several chart panels; leadership within a class depends on the chosen size boundary and tests.
Flint agent evaluations average pass@1 over at least five attempts, with timeouts up to five hours. Terminal-Bench uses Terminus 2 with internet access, but retrieval-obtained solutions count as failures; SWE-bench uses mini-swe-agent without internet. Not all comparison models were rerun by the same team. These results therefore cannot enter our existing AA general index, Pi/high task set or physical video-continuation board: task, harness and benchmark versions differ.
Sources and further reading
- Recursive: introducing FlintPublisher article · October 21Model aims, speed charts, evaluation settings and the claimed role of Eureka Machine in development.
- Flint model card and complete evaluation chartOfficial model card · pinned revision39.8B total and roughly 2.5B active parameters; text input/output, a 262,144-token configuration, BF16 serving and evaluation limits.
Fast generation is one part of a complete task
The original table separates an M4 Pro with 48GiB: Flint through MLX reaches 131.22 tokens/s at 1K input, versus a normalized mean of 68.89 through 128K. Its llama.cpp path records 87.98 and 47.58 respectively. Short-prompt speed does not extend unchanged to a long repository, and excludes prompt processing, tools, tests and retries. Time to a complete result matters more to a workflow than how quickly text appears.
The pinned rec README supports M4 Pro, M5 Pro or M5 Max, requiring at least 48GB unified memory and roughly 30GB free disk, optimized for a single session. Ollama’s approximately 23GB file and the roughly 80GB BF16 download are different recipes, not contradictory total-memory requirements. The launch article states up to 512k and recommends staying within 256k; the pinned card and configuration checked here specify 262,144 tokens shared by prompt and output. Use the downloaded revision and runtime settings, rather than reserving the entire advertised maximum for input.
Sources and further reading
- Recursive: introducing FlintPublisher article · October 21Model aims, speed charts, evaluation settings and the claimed role of Eureka Machine in development.
- Flint model card and complete evaluation chartOfficial model card · pinned revision39.8B total and roughly 2.5B active parameters; text input/output, a 262,144-token configuration, BF16 serving and evaluation limits.
- rec: supported hardware and single-session conditionsOfficial repository README · pinned commitM4 Pro / M5 Pro / M5 Max, at least 48GB unified memory and about 30GB disk; distinct from model capability.
- Context in the pinned weight configurationOfficial configurationmax_position_embeddings is 262144; prompt and generated output share the window.
- Flint distribution through OllamaRuntime platform pageCurrent latest/40b entries show an approximately 23GB file and 256K window; file size is not total runtime memory.
Automated research is worth following; daily use still needs a complete result
A second thread is Recursive’s claim that Eureka Machine helped explore architecture, quantization, kernels, data and training recipes. The article describes searching from a 35B-total, 3B-active baseline, then using the 16-bit model as a teacher to recover quantization quality. This connects automated research with local speed, but the under-four-month development account and causal attribution remain publisher claims, not proof of an entirely human-free process.
If suitable hardware is already available, a small task with a known acceptance condition can clarify the trade-off: reproduce a bug, fix it and run the relevant tests. Keep the inspected files, edits, recovery from failure and time to completion, then compare with a familiar tool. This is a proposed observation, not a test we performed. The useful follow-up is whether a portion of coding work can reliably finish locally, and how much guidance it requires.
Sources and further reading
- Recursive: introducing FlintPublisher article · October 21Model aims, speed charts, evaluation settings and the claimed role of Eureka Machine in development.
- Flint model card and complete evaluation chartOfficial model card · pinned revision39.8B total and roughly 2.5B active parameters; text input/output, a 262,144-token configuration, BF16 serving and evaluation limits.
- rec: supported hardware and single-session conditionsOfficial repository README · pinned commitM4 Pro / M5 Pro / M5 Max, at least 48GB unified memory and about 30GB disk; distinct from model capability.