DeepSeek official model repository · Published 2026-08-31
DeepSeek’s vision experiment: images in agent tasks
DeepSeek-V4-Flash-Vision-Exp adds visual modules to V4-Flash and releases weights, prompt encoding and reference inference code. It provides a way to study image-based agent tasks, while distinguishing a readable implementation from production serving.
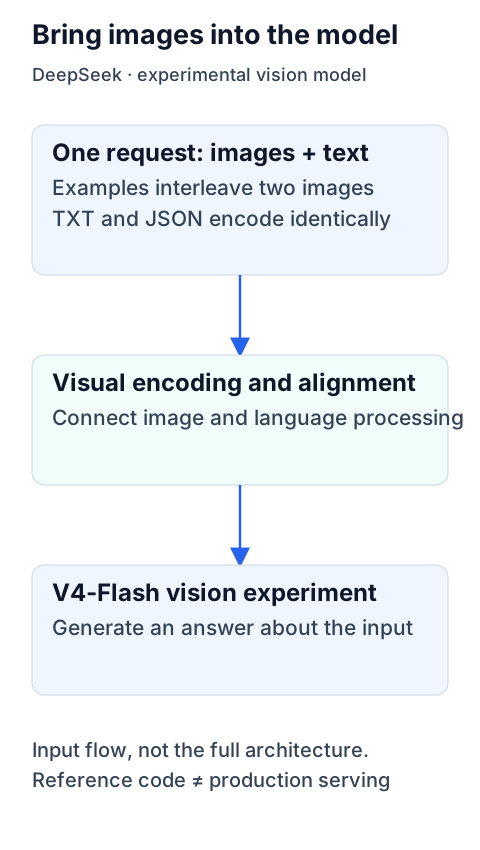
Bring images and text into one task
The official examples interleave two images with text. JSON content blocks and a TXT format containing image paths produce identical prompts and input token IDs. A vision encoder and aligner connect image processing to the language model. Comparing two device screenshots illustrates a possible input structure; it is not a BitShovel test.
The model card reports multimodal agent benchmarks and notes that V4-Flash-0731 ignores image inputs in two comparisons. Scores depend on input conditions and evaluation settings, so they do not predict gains on every image-based task.
Choose how to run the released implementation
The MIT-licensed repository includes minimal PyTorch inference. Its README explicitly distinguishes reference code from a production serving engine. Setup includes installing dependencies, converting weights and running equivalent TXT or JSON examples. The generation loop uses straightforward autoregressive sampling; including the DSpark forward path does not establish a fully optimized serving loop.
Separate vLLM and SGLang guides cover serving. The vLLM example uses one 4×GB300 node, not a minimum-hardware requirement. This experimental release is distinct from the later V4.1 Flash release and pricing. Assess output quality, latency and resource use on the intended task.
Important additions and corrections
Dates below mark changes to our coverage.
- Addition ·
Added image/text encoding and reference inference; separated experimental code, production serving and later releases.
- Addition ·
Added deployment conditions: the official example uses 4×GB300, which is not a minimum specification; experimental benchmarks do not replace task testing.
Sources and notes
sources中文
Sources and notes
- Read the originalDeepSeek official model repository
- DeepSeek inference guide
Retained summary and context
The model is experimental and minimal inference is not a production serving engine. The 4×GB300 configuration is a vLLM example, not a minimum. Cost and reliability remain untested by BitShovel.
Sources and evidence · 3 links
Each link has a purpose and scope. Link counts do not establish independent confirmation; direct support applies only to the statements specified below.
- DeepSeek official model repositoryDirect support
Grounded in the official model card and inference README. September 6 is a verification date; retain publishedAt=2026-08-31T10:13:34.000Z. Deployment examples do not establish consumer-machine readiness. Remove download and vote counts as readiness evidence. Fetch records are mapped by signalId in evidence-manifest.json.
Limits: The official vLLM example uses one 4×GB300 node; it is not a minimum-hardware specification. Other configurations require checking the deployment guides. The model remains experimental, and we have not tested deployment cost or reliability.
Source timeline
- · Entered the BitShovel radar: 25 entries visible on Reddit r/LocalLLaMA at collection, multiple same-day community threads; recheck found no new or metadata-updated entries.
- · Release watch (DeepSeek): market chatter captured via AIHOT featured (headline in Chinese).
- · Comparison (DeepSeek): "Apodex 1.1 Beats DeepSeek on Real-World Agentic " — lead via AlphaSignal daily. Same-class comparisons and sentiment signal the market's relative standing.
Collection record
First discovered:
Collection and source publication have distinct dates.
Editorial record
Sources reviewed
· Beijing time (UTC+8)
Added image/text encoding and reference inference; separated experimental code, production serving and later releases. Event, discovery and collection dates remain unchanged.
Sources and full record
This dates our review of the wording and sources, not a project release or product update.
Full record: before, after and sources (JSON)