Anthropic research announcement · Published 2026-08-27
Anthropic enables outside research on aggregate Claude usage
Anthropic’s pilot lets outside teams ask their own questions and analyze aggregate Claude usage. Neither the researchers nor users of the public dataset receive raw conversations.
Three teams, three questions
The August 26 announcement describes Stanford SALT Lab studying human–AI collaboration, Oxford’s Human Information Processing Lab studying experience and model behavior, and METR estimating coding-agent productivity. Each project analyzed roughly 250,000 Claude.ai or Claude Code conversations from April–May 2026.
The announcement linked SALT’s paper, while the Oxford and METR writeups were still in preparation. Public aggregate data and preliminary findings do not mean all three complete studies had been published.
Questions in, aggregates out
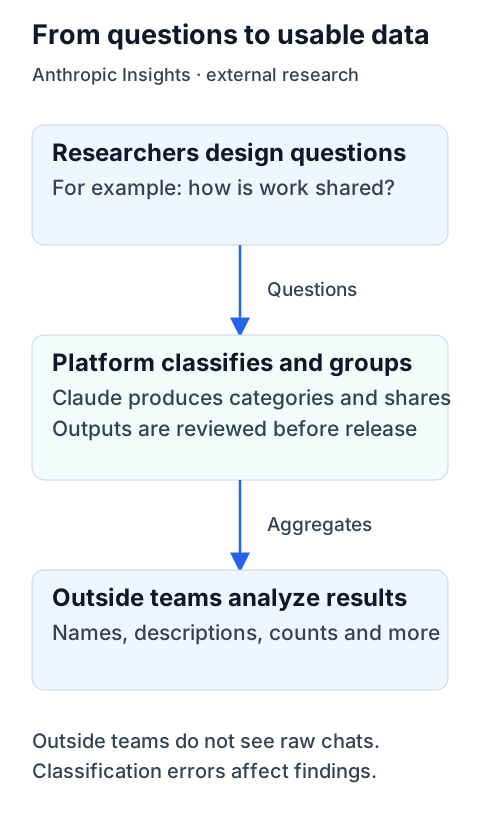
Researchers design questions; Anthropic runs Insights classification and aggregation, reviews the outputs, and supplies them for independent analysis. The public dataset contains category names, descriptions and counts, rather than chat transcripts. Anthropic says researchers may publish unfavorable findings, subject to review for privacy, confidential information, misuse-related information and research accuracy.
The arrangement gives outside teams more control over the questions, while interpretation still depends on Claude’s classifications. Researchers cannot inspect the underlying conversations to check individual errors. Read the questions, sample scope and category descriptions together; a model-generated label is not a manually confirmed fact.
Important additions and corrections
Dates below mark changes to our coverage.
- Correction ·
Corrected access and publication scope: outside teams receive aggregates, not raw chats; two complete writeups were still in preparation.
Sources and notes
sources中文
Sources and notes
- Read the originalAnthropic research announcement
- Anthropic public aggregate dataset
Retained summary and context
In-post points: (1) three external institutions designed their own studies on aggregated real Claude usage via Anthropic Insights (formerly Clio), with public results; (2) Anthropic calls this the first public independent studies on an AI company's own usage data; (3) a privacy appendix and interest form accompany the program.
The platform runs and aggregates the analysis; researchers cannot inspect individual raw chats. Classification quality, sample scope and review terms affect interpretation.
Sources and evidence · 4 links
Each link has a purpose and scope. Link counts do not establish independent confirmation; direct support applies only to the statements specified below.
Source timeline
- · Found this reading link via AIHOT featured.
Collection record
First discovered:
Collection and source publication have distinct dates.
Editorial record
Corrected
· Beijing time (UTC+8)
Corrected access and publication scope: outside teams receive aggregates, not raw chats; two complete writeups were still in preparation. Event, discovery and collection dates remain unchanged.
Sources and full record
This dates our review of the wording and sources, not a project release or product update.
Full record: before, after and sources (JSON)