Qwen official blog via AIHOT featured · Published 2026-08-26
Qwen3.8-Flash-Next weights offer a Qwen4 architecture preview
Qwen3.8-Flash-Next offers experimental weights with a vision encoder, previewing Qwen4 architecture. Its parameter figures describe different components.
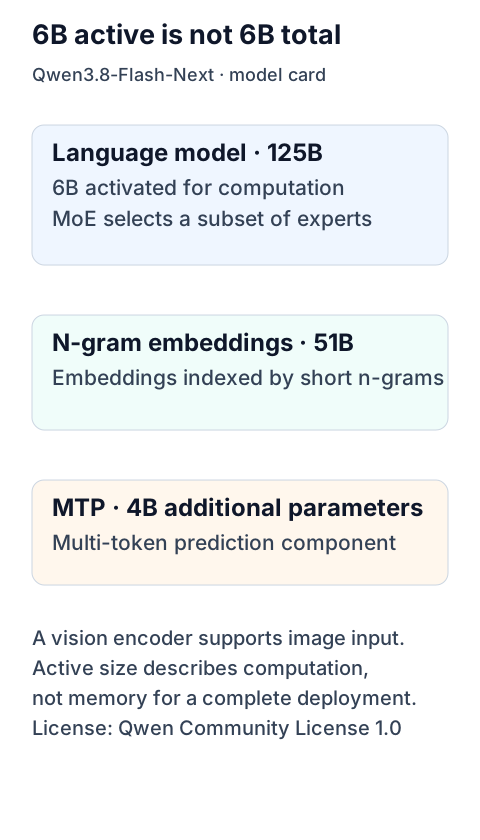
Active parameters versus stored weights
The model card lists 125B language-model parameters, 6B active, plus 51B n-gram embeddings and 4B MTP parameters. MoE selects part of the experts for computation; active size does not specify the memory required to store the weights.
Image-text input is supported. Qwen highlights sparse attention, gated residuals and n-gram embeddings as architectural changes. These figures alone are not a deployment memory estimate.
Weights versus the hosted service
Native context is 262,144 tokens, extensible to 1,000,000. The hosted Qwen3.8-Flash separately offers default 1M context and built-in tools; those service features should not be assumed in self-hosting.
Qwen Community License 1.0 includes separate commercial-permission requirements for defined model-service and AI-work-assistant businesses, with an internal-use exception. Consult its full terms. We have not measured deployment speed or cost.
Important additions and corrections
Dates below mark changes to our coverage.
- Addition ·
Separated parameter components, native context and hosted-service features, with model-card and license links.
- Correction ·
Added officially documented parameters and license conditions: 6B active parameters do not imply a 6B model’s memory needs, and some commercial uses require separate permission.
Sources and notes
sources中文
Sources and notes
- Read the originalQwen official blog via AIHOT featured
- Qwen official model card
- Qwen Community License 1.0
Retained summary and context
The 6B active figure does not imply a 6B model’s memory footprint. The release is experimental. Its license requires separate permission for commercial use by businesses offering model services or defined AI work assistants, with an internal-use exception. We have not tested performance or cost improvements.
Sources and evidence · 4 links
Each link has a purpose and scope. Link counts do not establish independent confirmation; direct support applies only to the statements specified below.
- Qwen official blog via AIHOT featuredDirect support
Current official model cards and the license supersede the unsupported-specification caveat. “Available weights” avoids implying a permissive open-source license. Retain publishedAt=2026-08-26T12:30:00.000Z. This review does not establish when the specifications first appeared; September 6 records verification only. Preserve historical release-day observations as such. See evidence-manifest.json.
Limits: The 6B active figure does not imply a 6B model’s memory footprint. The release is experimental. Its license requires separate permission for commercial use by businesses offering model services or defined AI work assistants, with an internal-use exception. We have not tested performance or cost improvements.
Source timeline
- · Found this reading link via AIHOT featured.
- · Verified here: the ModelScope model page is live under the official name (title read confirmed); TechNode relays the official schedule noting the FP8 pair while specs remain undisclosed.
- · Comparison (Qwen): "Opencode vs Deepseek harness: my experience with" — lead via Reddit r/LocalLLaMA. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "Alibaba's Qwen3.8-Max-0902 Tops Code Arena, Beat" — lead via alphasignal-daily. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "Perplexity's Lily Beats MLX-LM by 1.35x Running " — lead via alphasignal-daily. Same-class comparisons and sentiment signal the market's relative standing.
- · Release watch (Qwen): "Perplexity open-sourced their Mac inference serv" — lead via reddit-local-llama. Same-class release moves reshape expectations and alternatives.
- · Release watch (Qwen): "We open-sourced Paddock, our Rust/C++ inference " — lead via reddit-local-llama. Same-class release moves reshape expectations and alternatives.
- · Comparison (Qwen): "Updated my benchmark with a new vLLM based recip" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "I benchmarked 21 Qwen3.8 27B variants on 16GB VR" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "Qwen3.8-27B on 2× RTX 5070 Ti 16GB — llama.cpp v" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "NInfer vs llama.cpp vs vLLM: quality + speed com" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Release watch (Qwen): market chatter captured via ithome (headline in Chinese). Same-class release moves reshape expectations and alternatives.
- · Comparison (Qwen): "DeepSeek-V4-Flash-Vision Q8 vs Qwen3.8-Flash-Nex" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "exllamav3 comfortably beats llama.cpp running CP" — lead via reddit-local-llama. Same-class comparisons and sentiment signal the market's relative standing.
- · Comparison (Qwen): "Benchmarking Qwen3.8 27B quantizations: 4-bit ho" — lead via lobsters-hotstories. Same-class comparisons and sentiment signal the market's relative standing.
- · Release watch (Qwen): "Qwen3.8-Flash-Next on MLX-serve, 1m context is r" — lead via reddit-local-llama. Same-class release moves reshape expectations and alternatives.
Collection record
First discovered:
Collection and source publication have distinct dates.
Editorial record
Sources reviewed
· Beijing time (UTC+8)
Separated parameter components, native context and hosted-service features, with model-card and license links. Original publication, discovery and collection dates remain.
Sources and full record
This dates our review of the wording and sources, not a project release or product update.
Full record: before, after and sources (JSON)