Meta engineering blog via AIHOT featured · Published 2026-08-25
MetaRoCE puts congestion and path control at the endpoints
MetaRoCE moves congestion and path control to network endpoints. Meta reports 64-node validation and schedules the specification, implementation and compliance tools for an October OCP release.
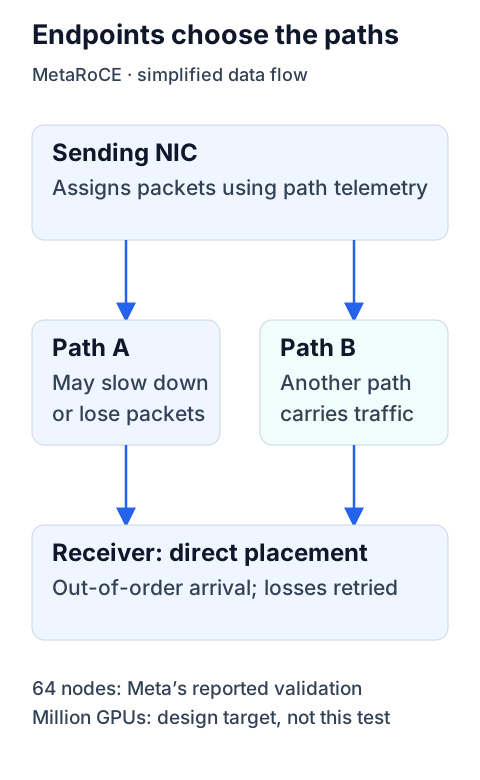
Separate paths, direct placement
Slow transfers can hold up collective GPU work. Endpoint NICs track each path’s congestion and latency, while receivers place out-of-order packets directly into their destination memory.
Acknowledgments identify missing packets for retransmission. The design tolerates loss without PFC pause frames, and multiple paths serve one connection.
Test scale and release timing
Meta compared RoCEv2 on a 64-node AMD GPU cluster, reporting about 86% throughput at 1% packet loss. Million-GPU scale is the design target, not the size of this test.
The August 24 article schedules the specification, reference implementation and compliance framework for the October OCP summit. This corrects the earlier claim that they were already released; downloadable versions and other vendors’ implementations need follow-up.
Important additions and corrections
Dates below mark changes to our coverage.
- Correction ·
Corrected timing and scale: release was planned for October; the reported cluster test used 64 nodes, while a million GPUs is a design target.
Sources and notes
sources中文
Sources and notes
- Read the originalMeta engineering blog via AIHOT featured
Retained summary and context
Test figures come from Meta’s 64-node cluster; a million GPUs is the design target. The article schedules release for October; this review does not establish an already downloadable release.
Sources and evidence · 2 links
Each link has a purpose and scope. Link counts do not establish independent confirmation; direct support applies only to the statements specified below.
Source timeline
- · Found this reading link via AIHOT featured.
Collection record
First discovered:
Collection and source publication have distinct dates.
Editorial record
Corrected
· Beijing time (UTC+8)
Corrected timing and scale: release was planned for October; the reported cluster test used 64 nodes, while a million GPUs is a design target. Original publication, discovery and collection dates remain.
Sources and full record
This dates our review of the wording and sources, not a project release or product update.
Full record: before, after and sources (JSON)